Category / devops observability
DevOps & observability
Delivery pipelines, production systems, reliability, and useful telemetry.
CI That Stops Rebuilding the World: Caching, Matrix Builds, and Flaky-Test Quarantine
Cut CI time with dependency and build caching that actually invalidates correctly, matrix builds that parallelise honestly, and a quarantine lane for flaky tests.
Multi-Stage Docker Builds for Node and Python: Smaller Images, Fewer Surprises
Learn multi-stage Docker builds for Node and Python with cache mounts, slim runtime images, non-root users, and digest pinning to cut bloat and build risk.
Grafana Dashboards That Answer Questions Instead of Displaying Data
Design Grafana dashboards around the questions operators actually ask: symptom-first layout, RED and USE panels, honest thresholds, and variables that narrow scope.
Runbooks That Get Used at 3 a.m.: Structure, Triggers, and the Last Verified Step
Write runbooks an exhausted engineer can execute at 3 a.m.: symptom-based triggers, numbered verifiable steps, explicit stop conditions, and a maintenance loop.
Kubernetes Probes Aren't Interchangeable: Liveness, Readiness, and Startup in Production
Learn what liveness, readiness, and startup probes actually control, how they fail in production, and how to configure all three correctly.
Prometheus Metrics That Don't Explode: Cardinality, Naming, and the Queries You'll Actually Run
Design Prometheus metrics that stay queryable under load: naming, label discipline, histograms, and the PromQL for errors, latency, and saturation.
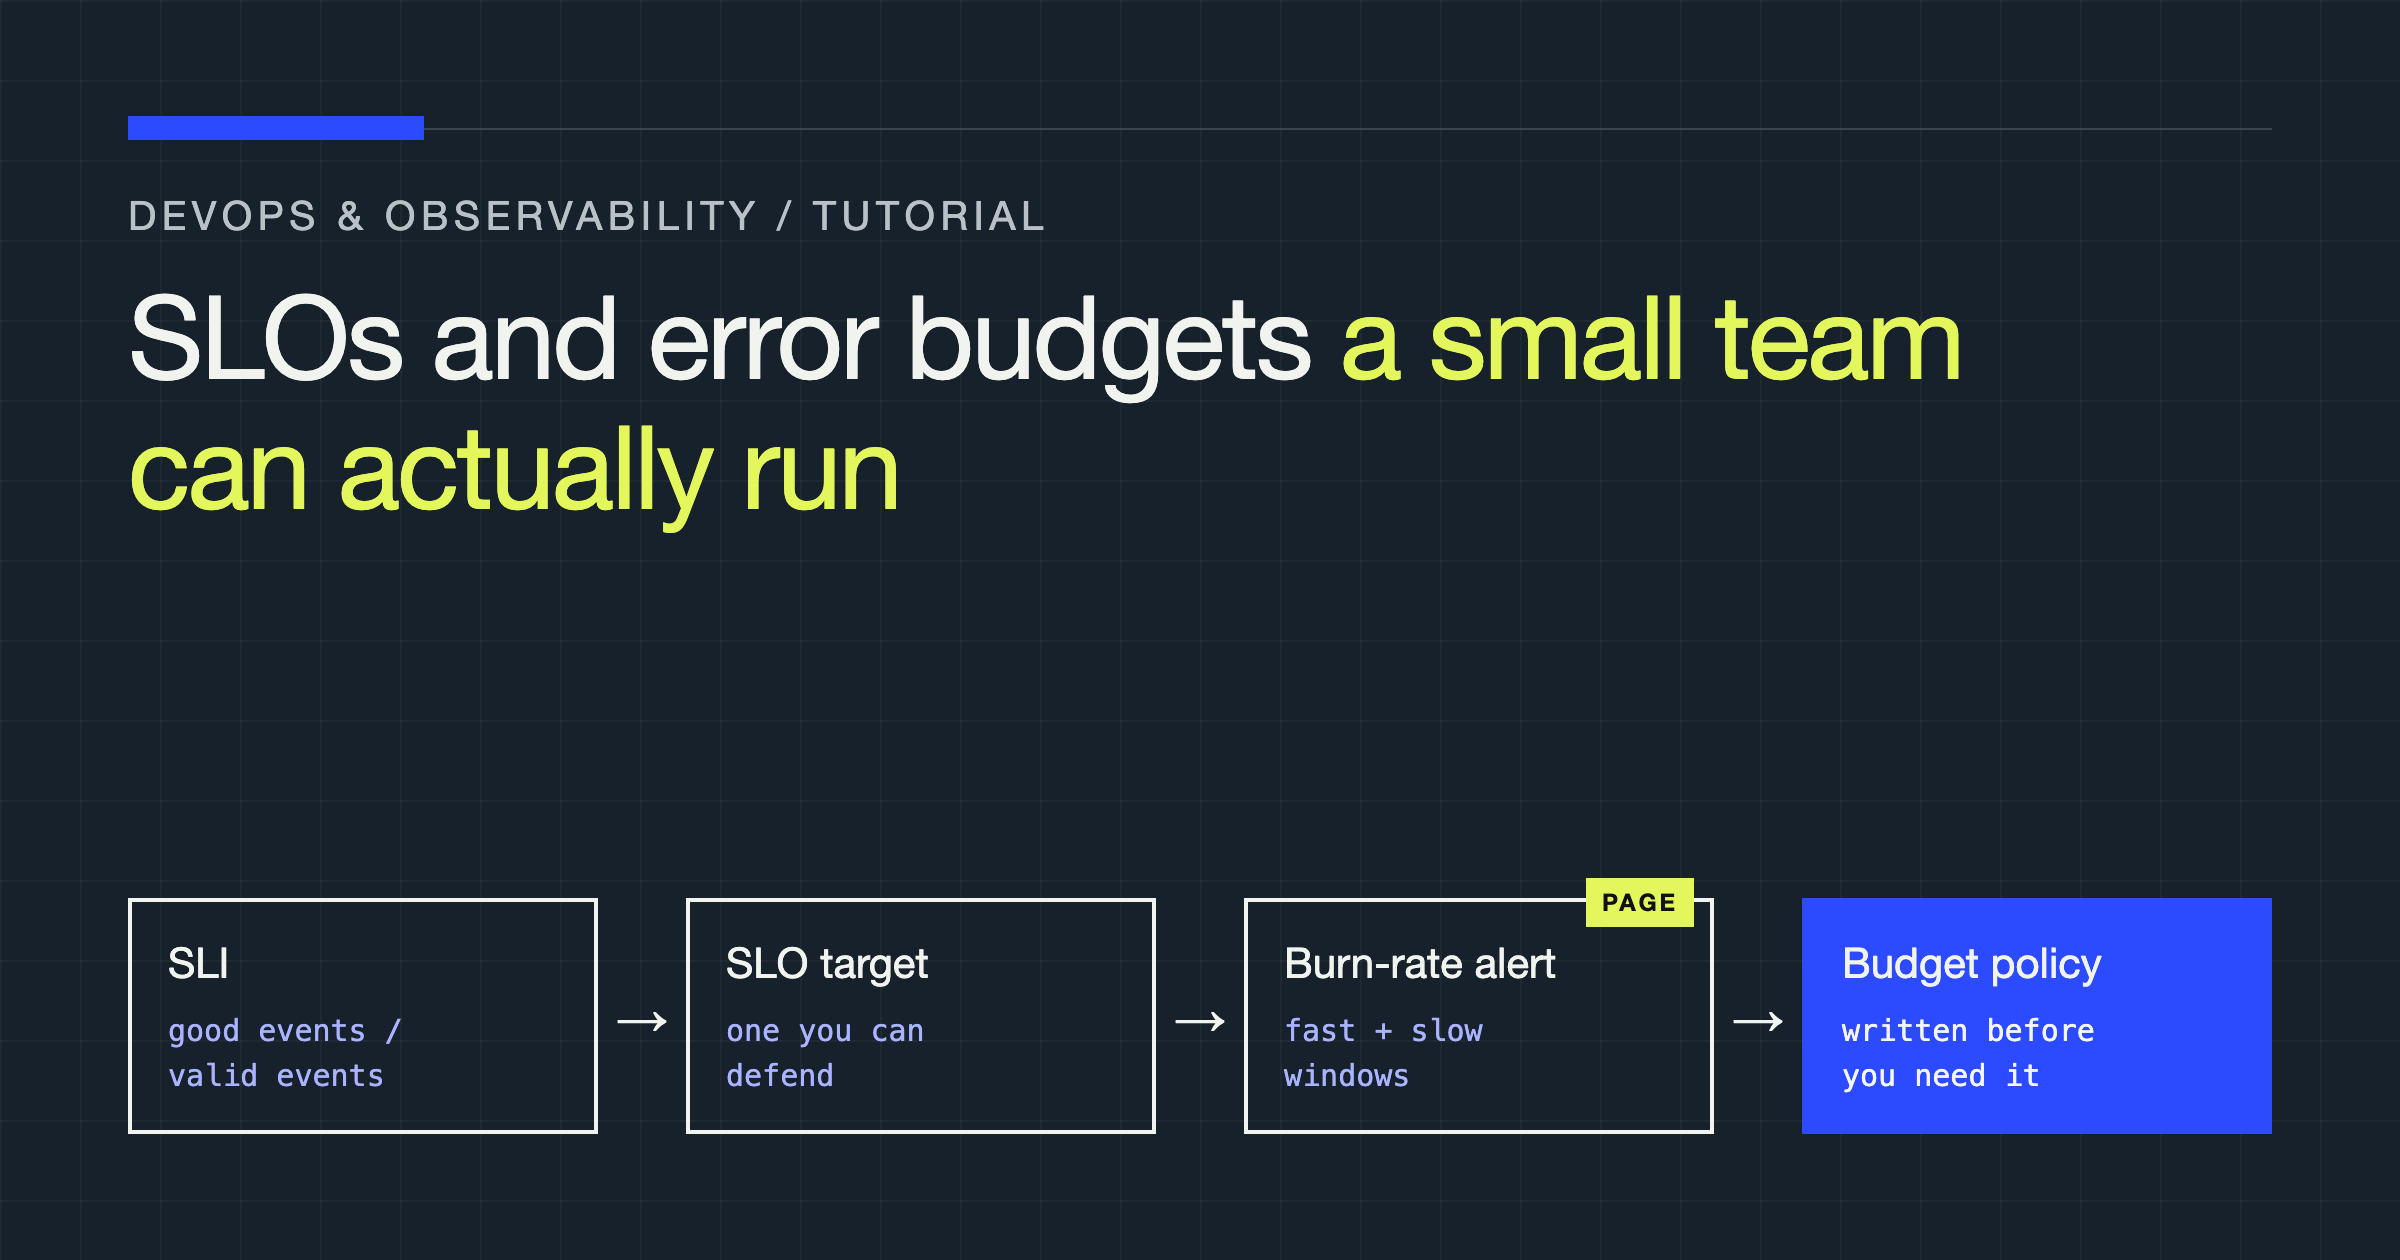
SLOs and Error Budgets a Small Team Can Actually Run
Build a lean SLO practice for a small team: pick few user-facing SLIs, set defensible targets, add burn-rate alerts, and enforce an error budget policy.
Structured Logging in Node.js That Pays Off During Incidents
Build structured JSON logging in Node.js with correlation IDs, redaction, and error serialization so you can trace failures quickly during incidents.
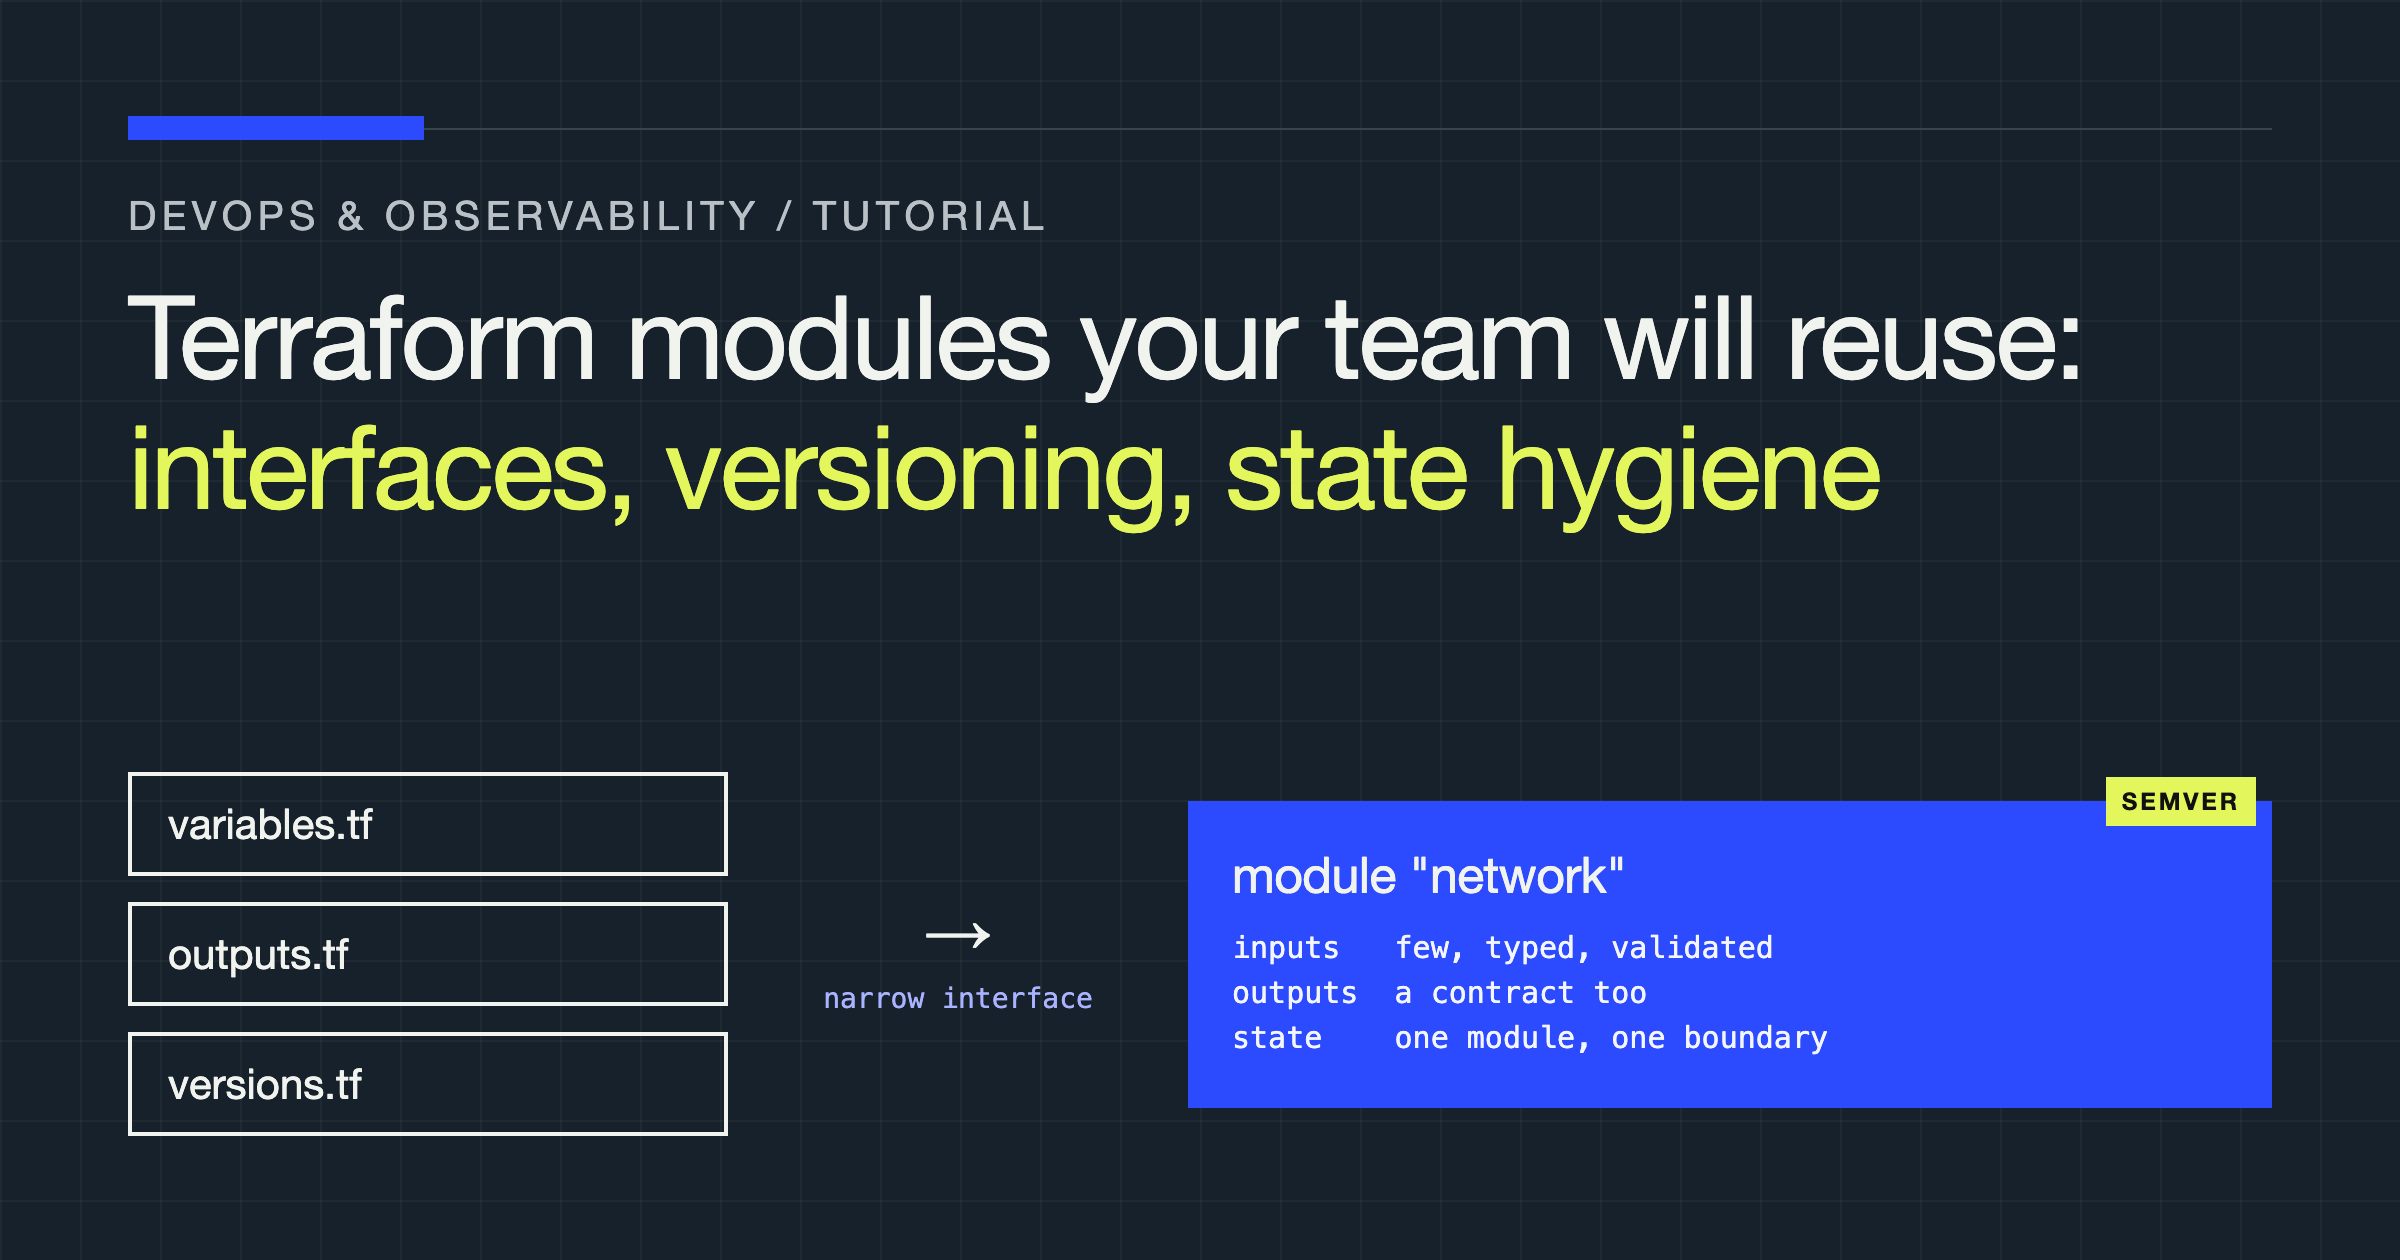
Terraform Modules Your Team Will Reuse: Interfaces, Versioning, and State Hygiene
Design Terraform modules with narrow interfaces, honest versioning, and clean state boundaries so other teams adopt them instead of copying and forking them.
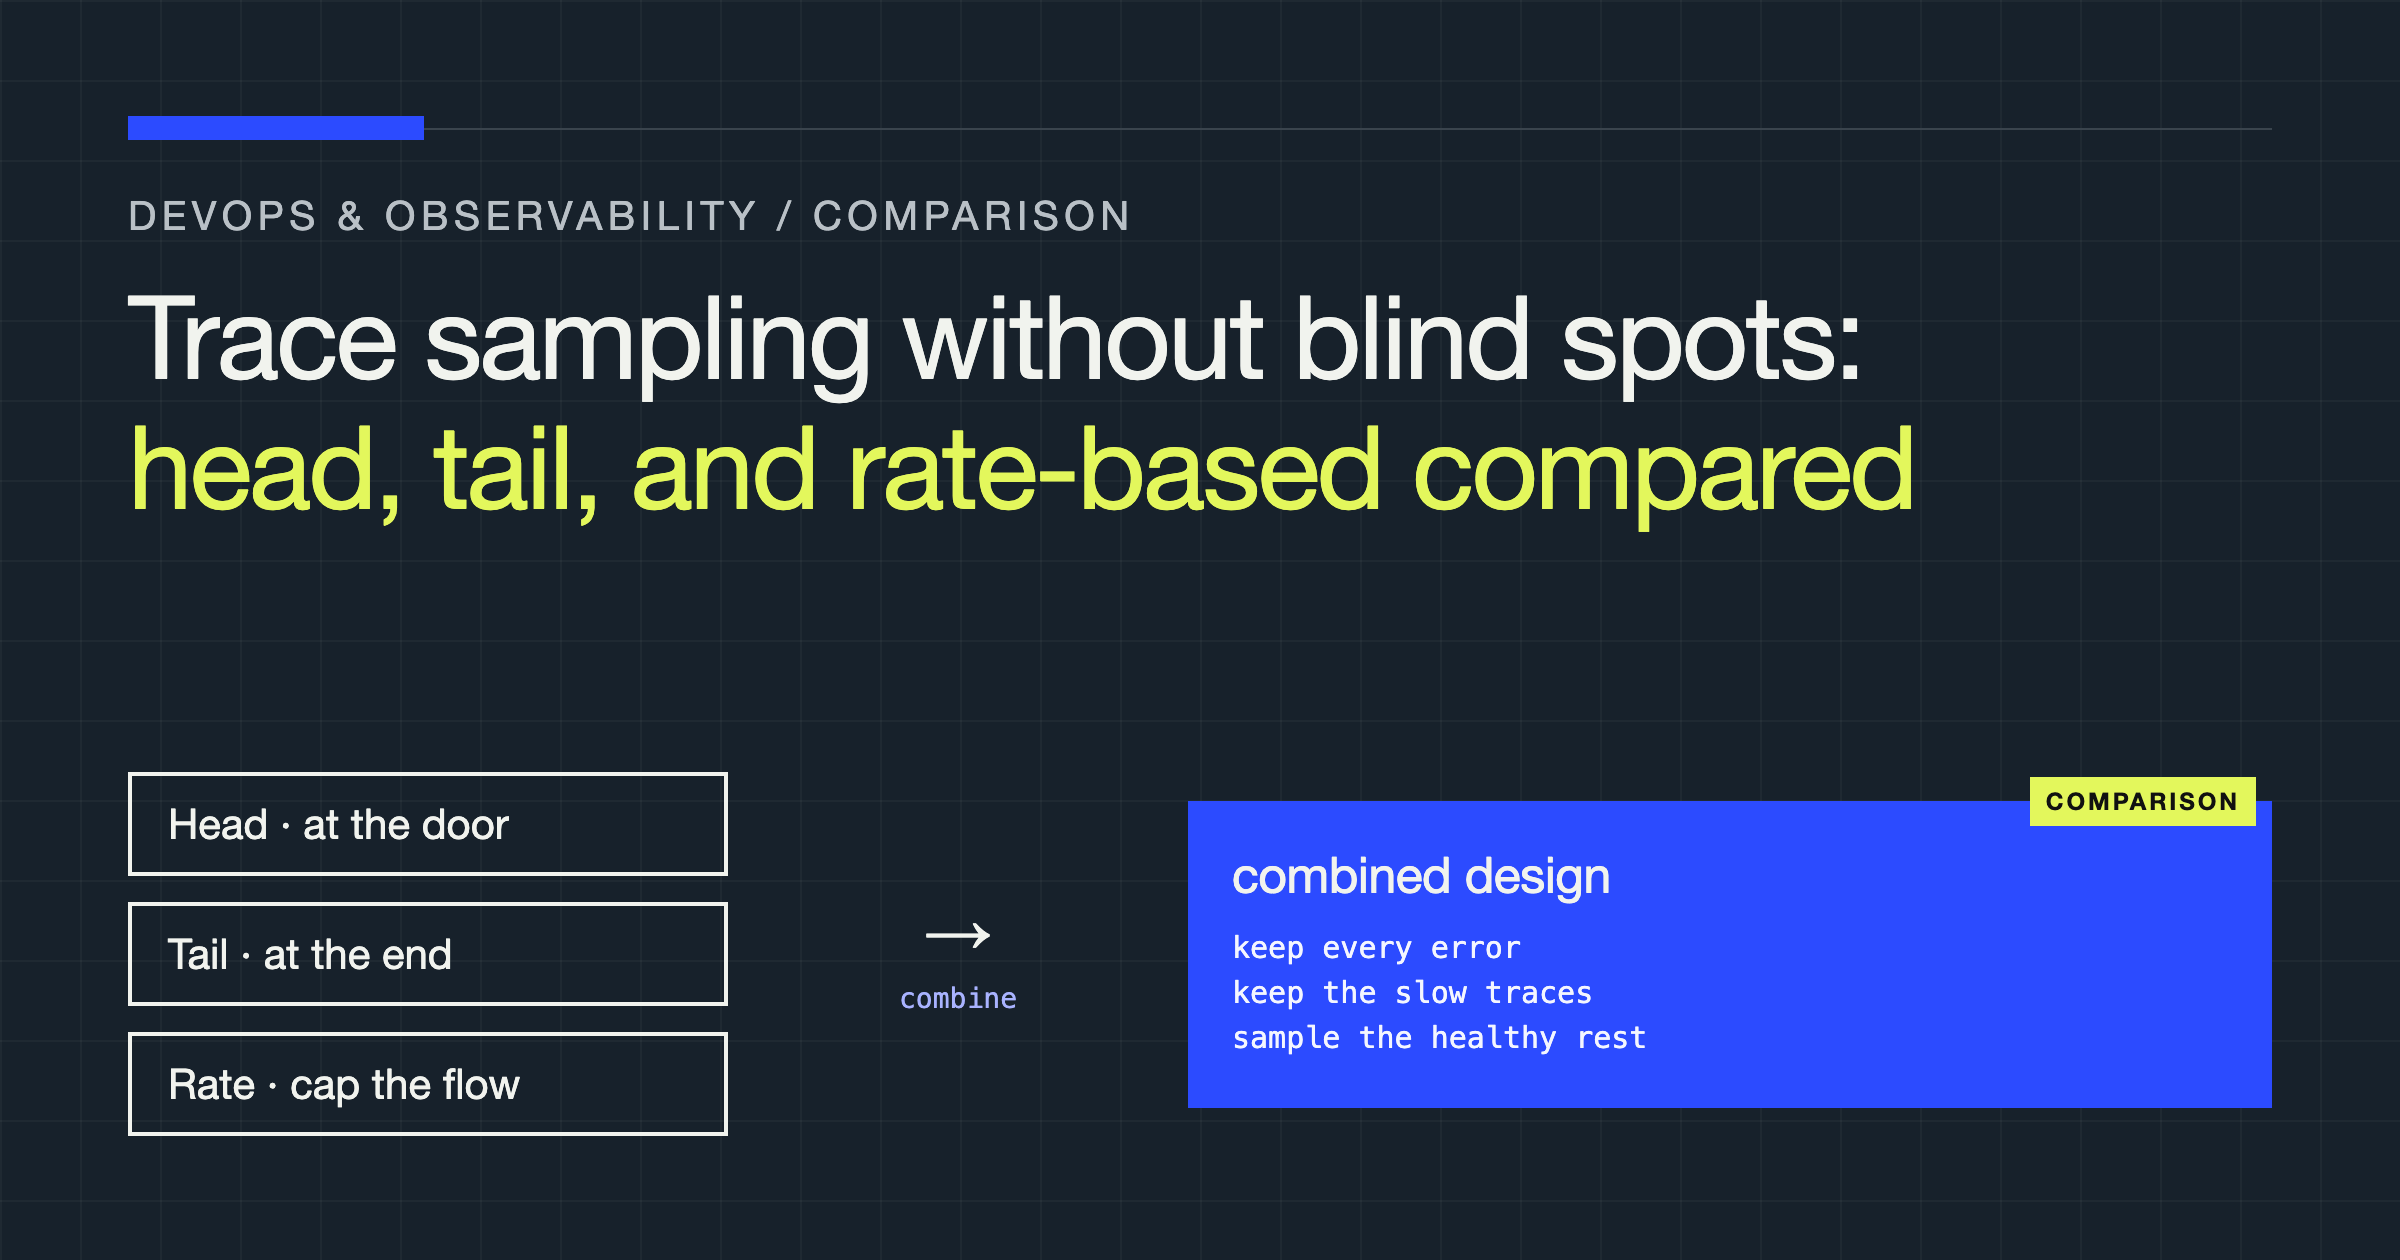
Trace Sampling Without Blind Spots: Head, Tail, and Rate-Based Strategies Compared
Compare head, tail, and rate-based trace sampling by what each keeps, what each silently drops, and how to combine them without losing the traces that matter.
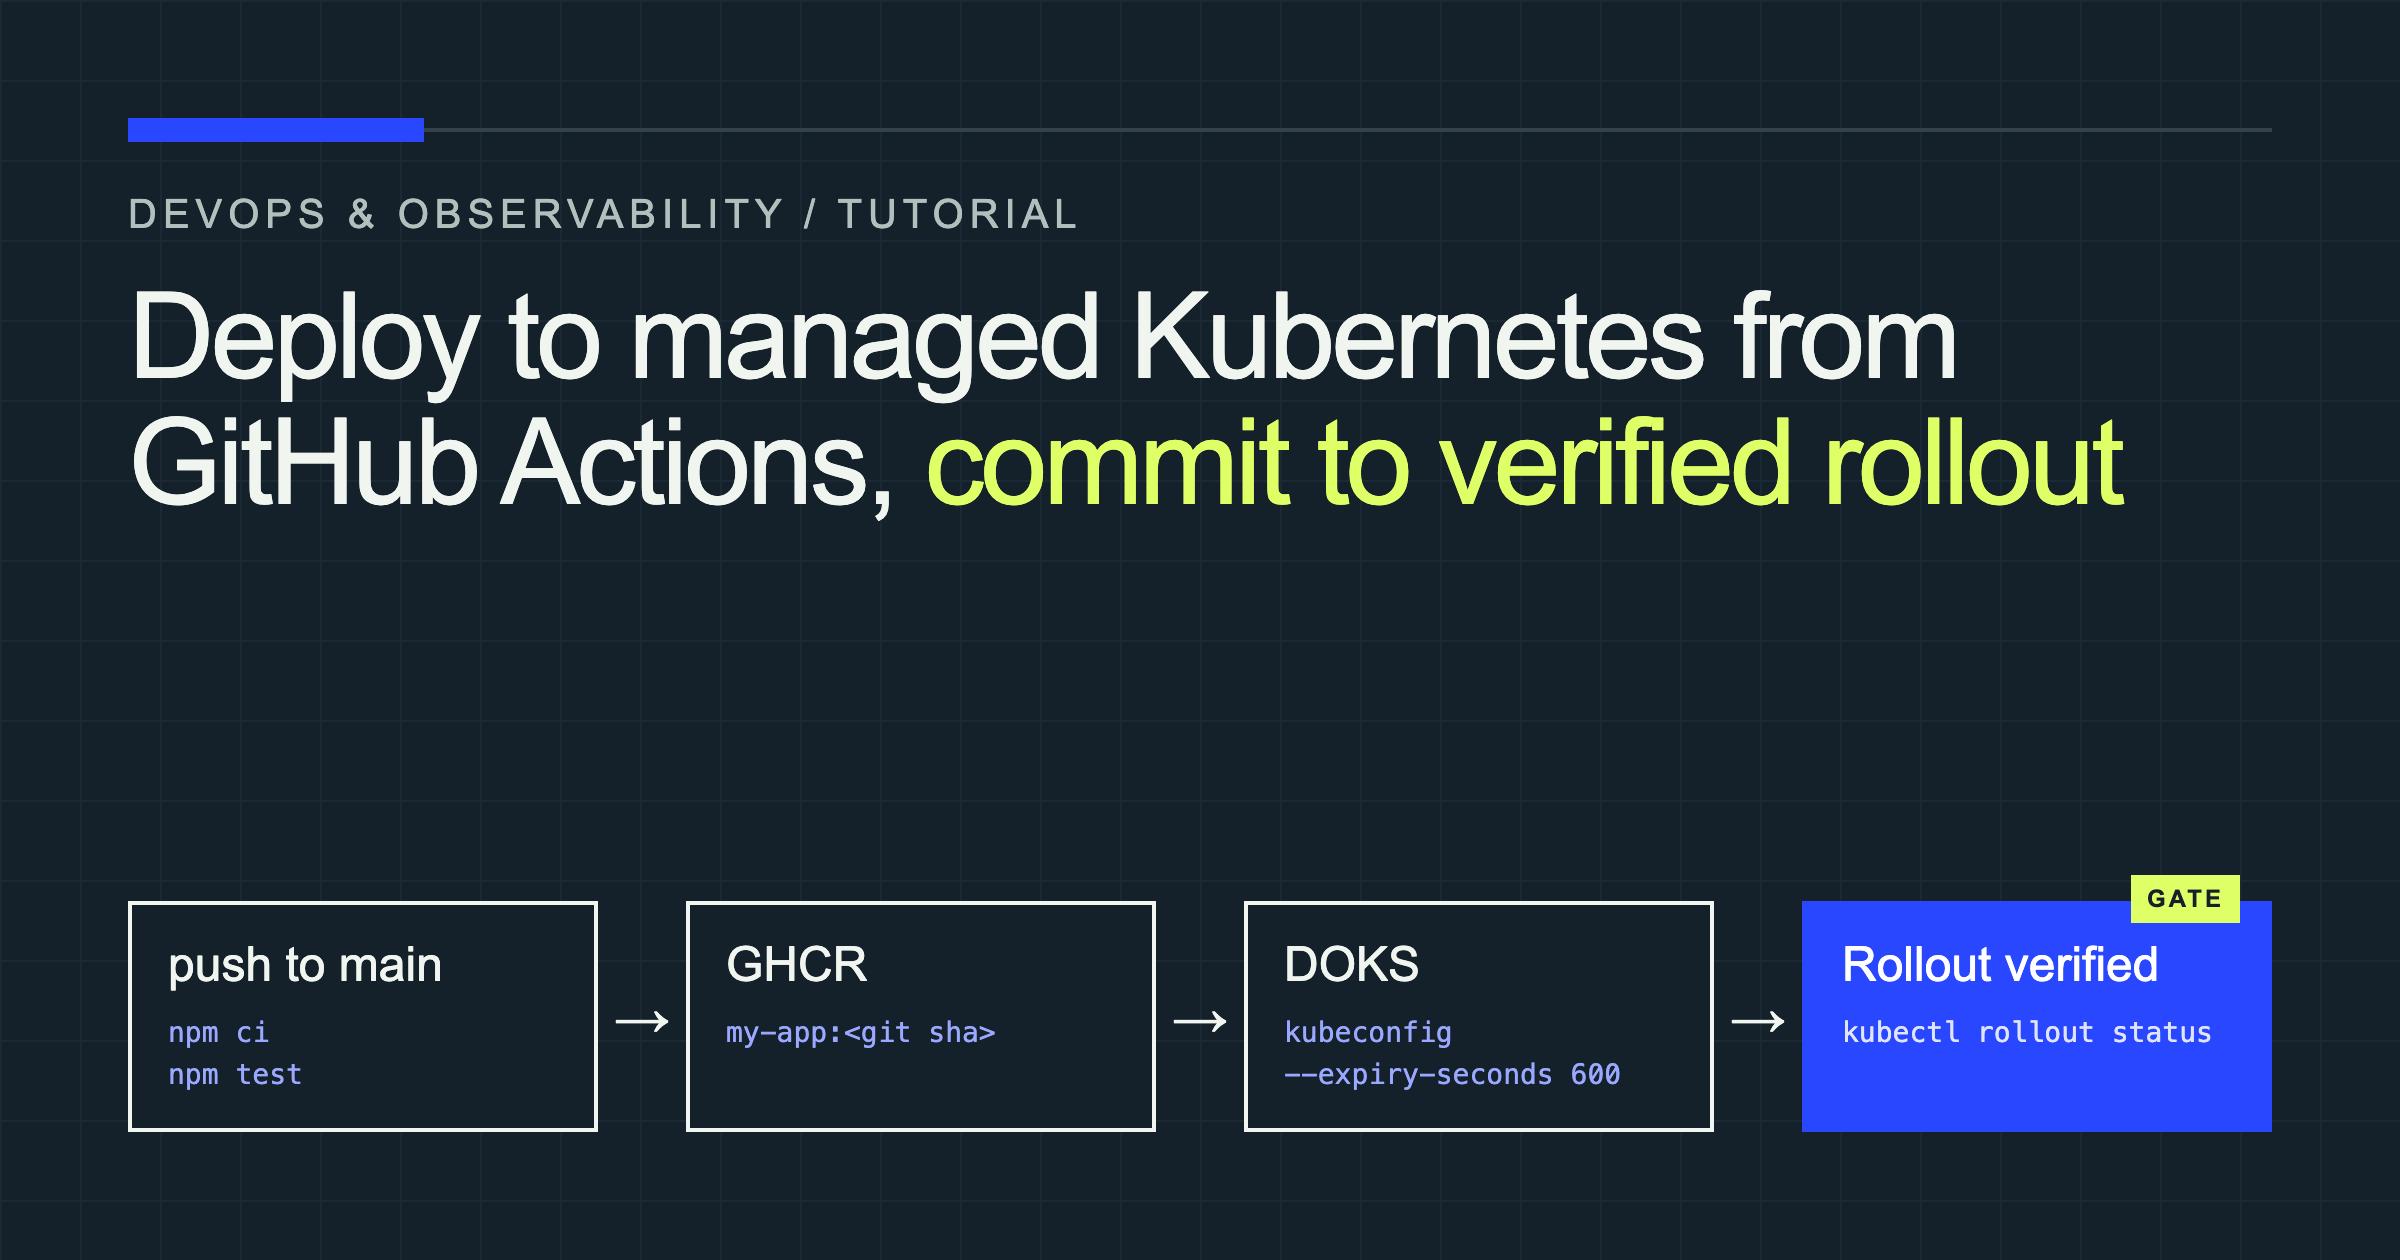
Deploy to Managed Kubernetes from GitHub Actions: A Complete CI/CD Walkthrough
Build a GitHub Actions pipeline that tests a Node.js app, publishes its Docker image to GHCR, and deploys it to DigitalOcean Kubernetes.
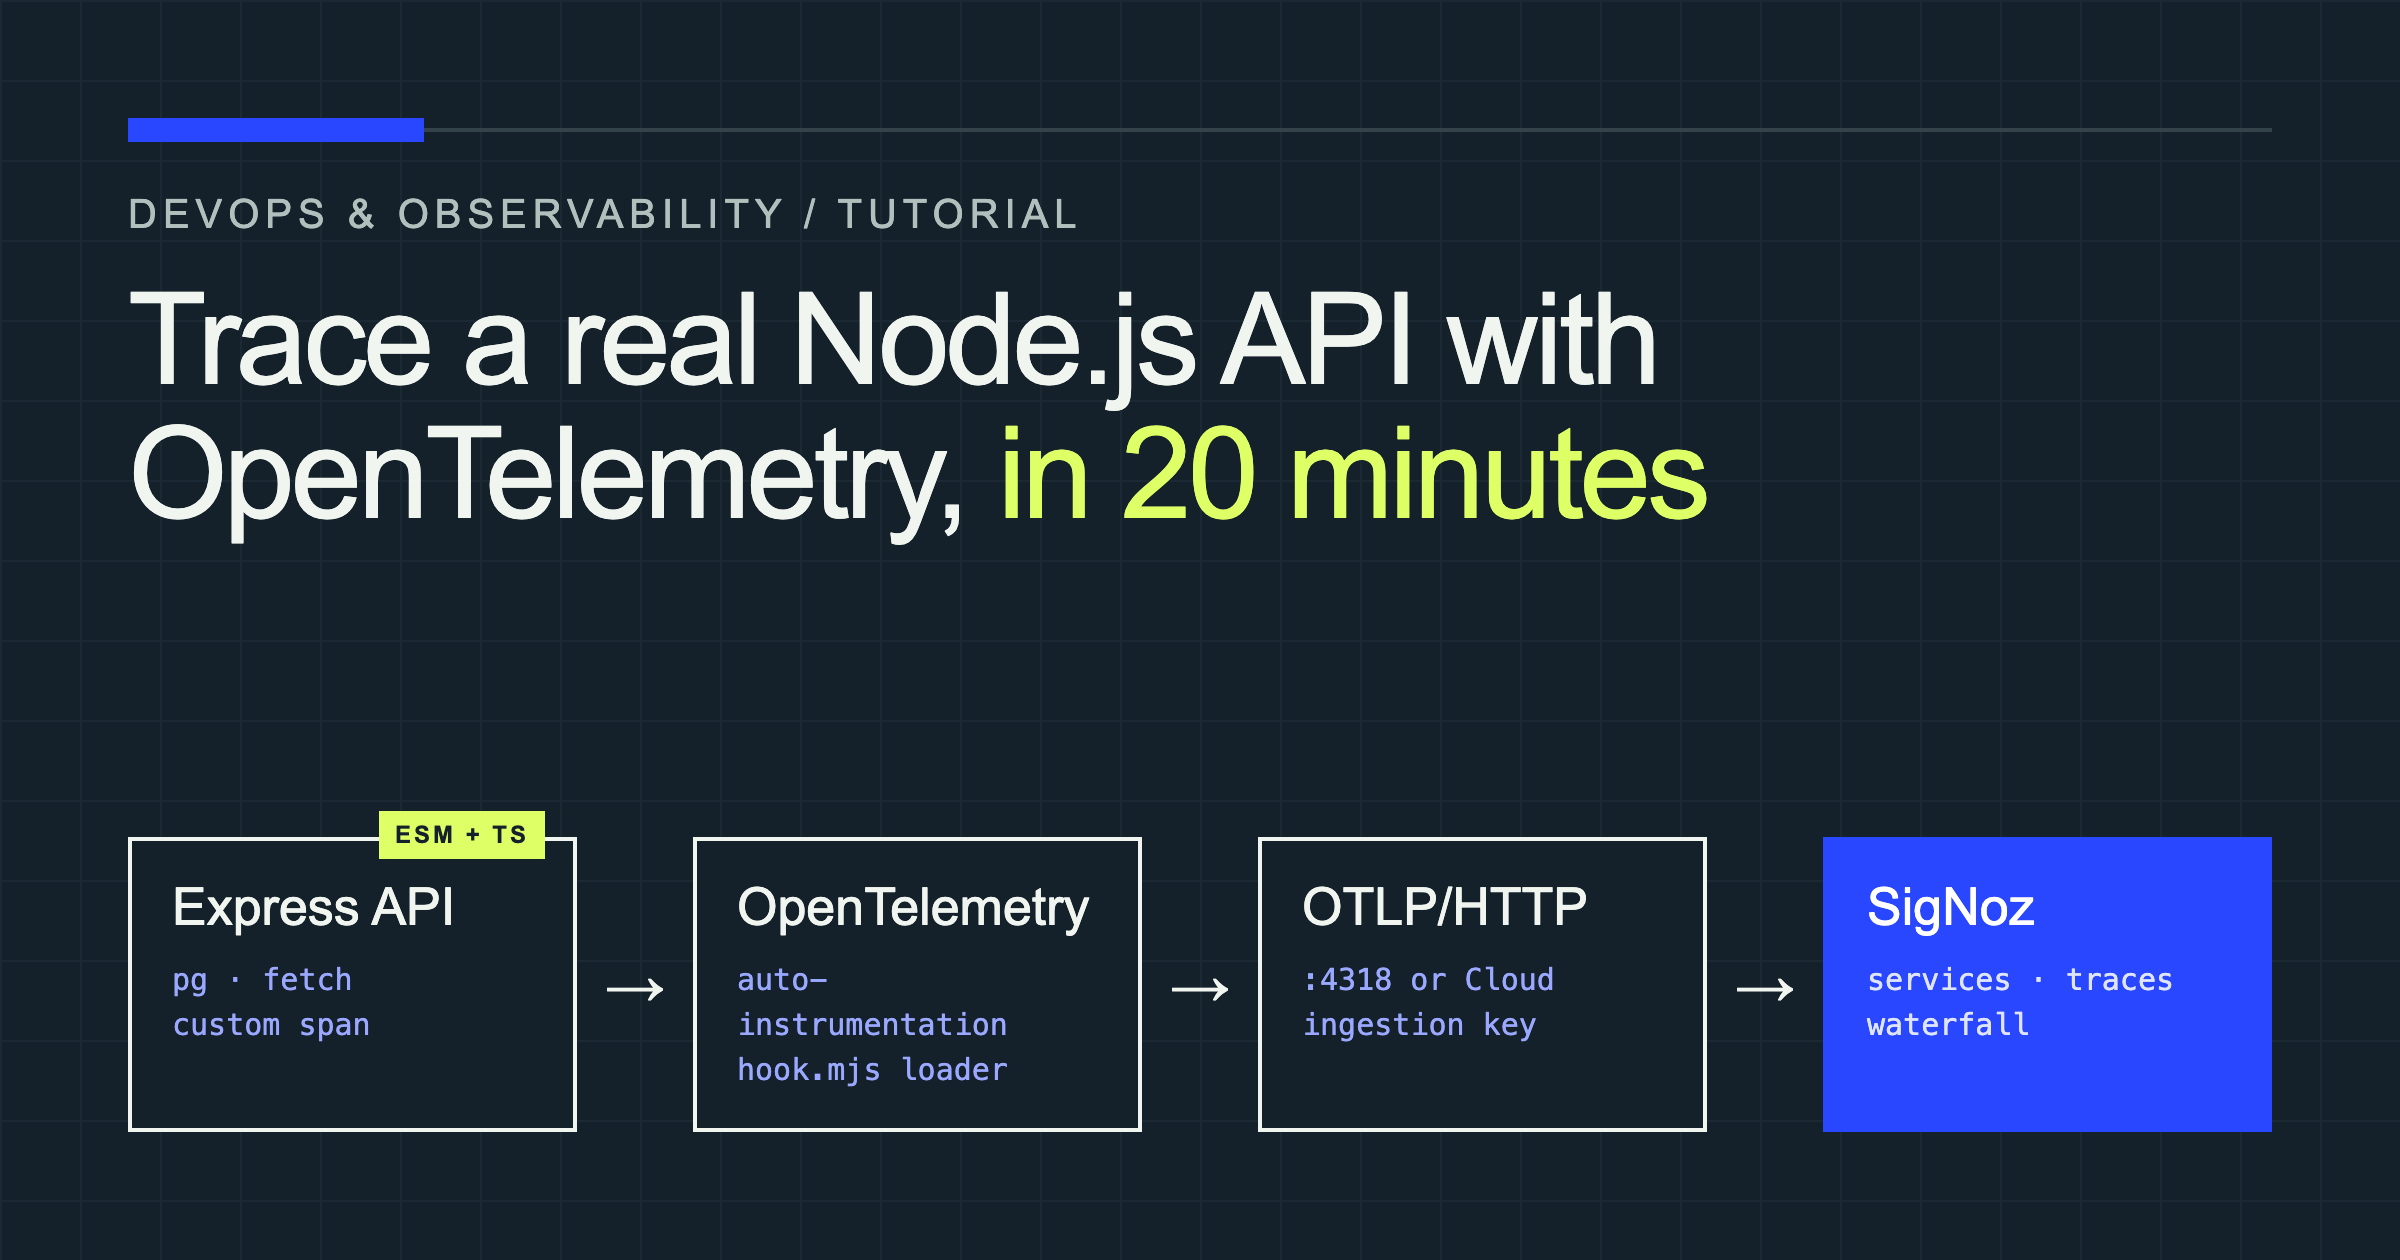
Trace a Real Node.js API with OpenTelemetry and SigNoz in 20 Minutes (ESM and TypeScript Included)
Trace Express, Postgres, outbound HTTP calls, and custom business logic with OpenTelemetry and SigNoz, including the correct ESM and TypeScript setup.
No matches in this set.
Clear a filter or try another combination.