Category / data engineering
Data engineering
Pipelines, warehouses, streaming systems, and the decisions behind them.
BigQuery Partitioning and Clustering: The Cost Decisions You Make at Table-Creation Time
Partition and cluster BigQuery tables with intent: how pruning actually works, where each feature stops helping, and the decisions that are painful to reverse later.
Dagster vs Airflow for a New Data Platform: Assets, Sensors, and Day-Two Operations
Dagster and Airflow compared on assets, sensors, partitions, backfills, retries, and observability, so you can choose the right core for a new platform.
Data Quality Gates with Great Expectations: Expectations, Checkpoints, and CI
Build a working data quality gate with Great Expectations: define an Expectation Suite, run it as a Checkpoint, store the results, and fail CI on bad data.
Incremental Models in dbt: Merge Strategies, Late Data, and Full-Refresh Discipline
Choose the right dbt incremental strategy, handle late-arriving data with lookback windows, and build the full-refresh habits that keep incremental models trustworthy.
dbt Tests and Data Contracts: Catching Upstream Breakage Before Your Stakeholders Do
Layer dbt generic, singular, and unit tests with enforced data contracts so upstream schema and logic changes fail in CI, not in a stakeholder's dashboard.
Change Data Capture with Debezium: From Postgres WAL to a Consumer That Keeps Up
Stand up Debezium on Postgres logical decoding, protect the replication slot, and write a consumer that handles snapshots, deletes, and schema changes without losing rows.
Kafka Delivery Semantics in Practice: What Exactly-Once Actually Buys You
At-most-once, at-least-once, and exactly-once in Kafka, precisely: which configurations deliver which guarantee, where exactly-once stops, and what to build instead.
Schema Evolution Without Breaking Consumers: Avro, Protobuf, and Compatibility Modes
A practical guide to evolving Avro and Protobuf schemas safely with compatibility modes, registries, and expand-and-contract deployments.
Streaming vs Batch: Choosing with a Latency Budget Instead of a Trend
Choose between streaming, micro-batch, and batch by deriving a latency budget from the consumer decision, not by following tooling trends.
Warehouse Cost Control: The Queries, Habits, and Guardrails That Cut the Bill
Cut warehouse spend by finding expensive queries, fixing pruning and sizing, and adding guardrails that stop waste before it becomes the bill.
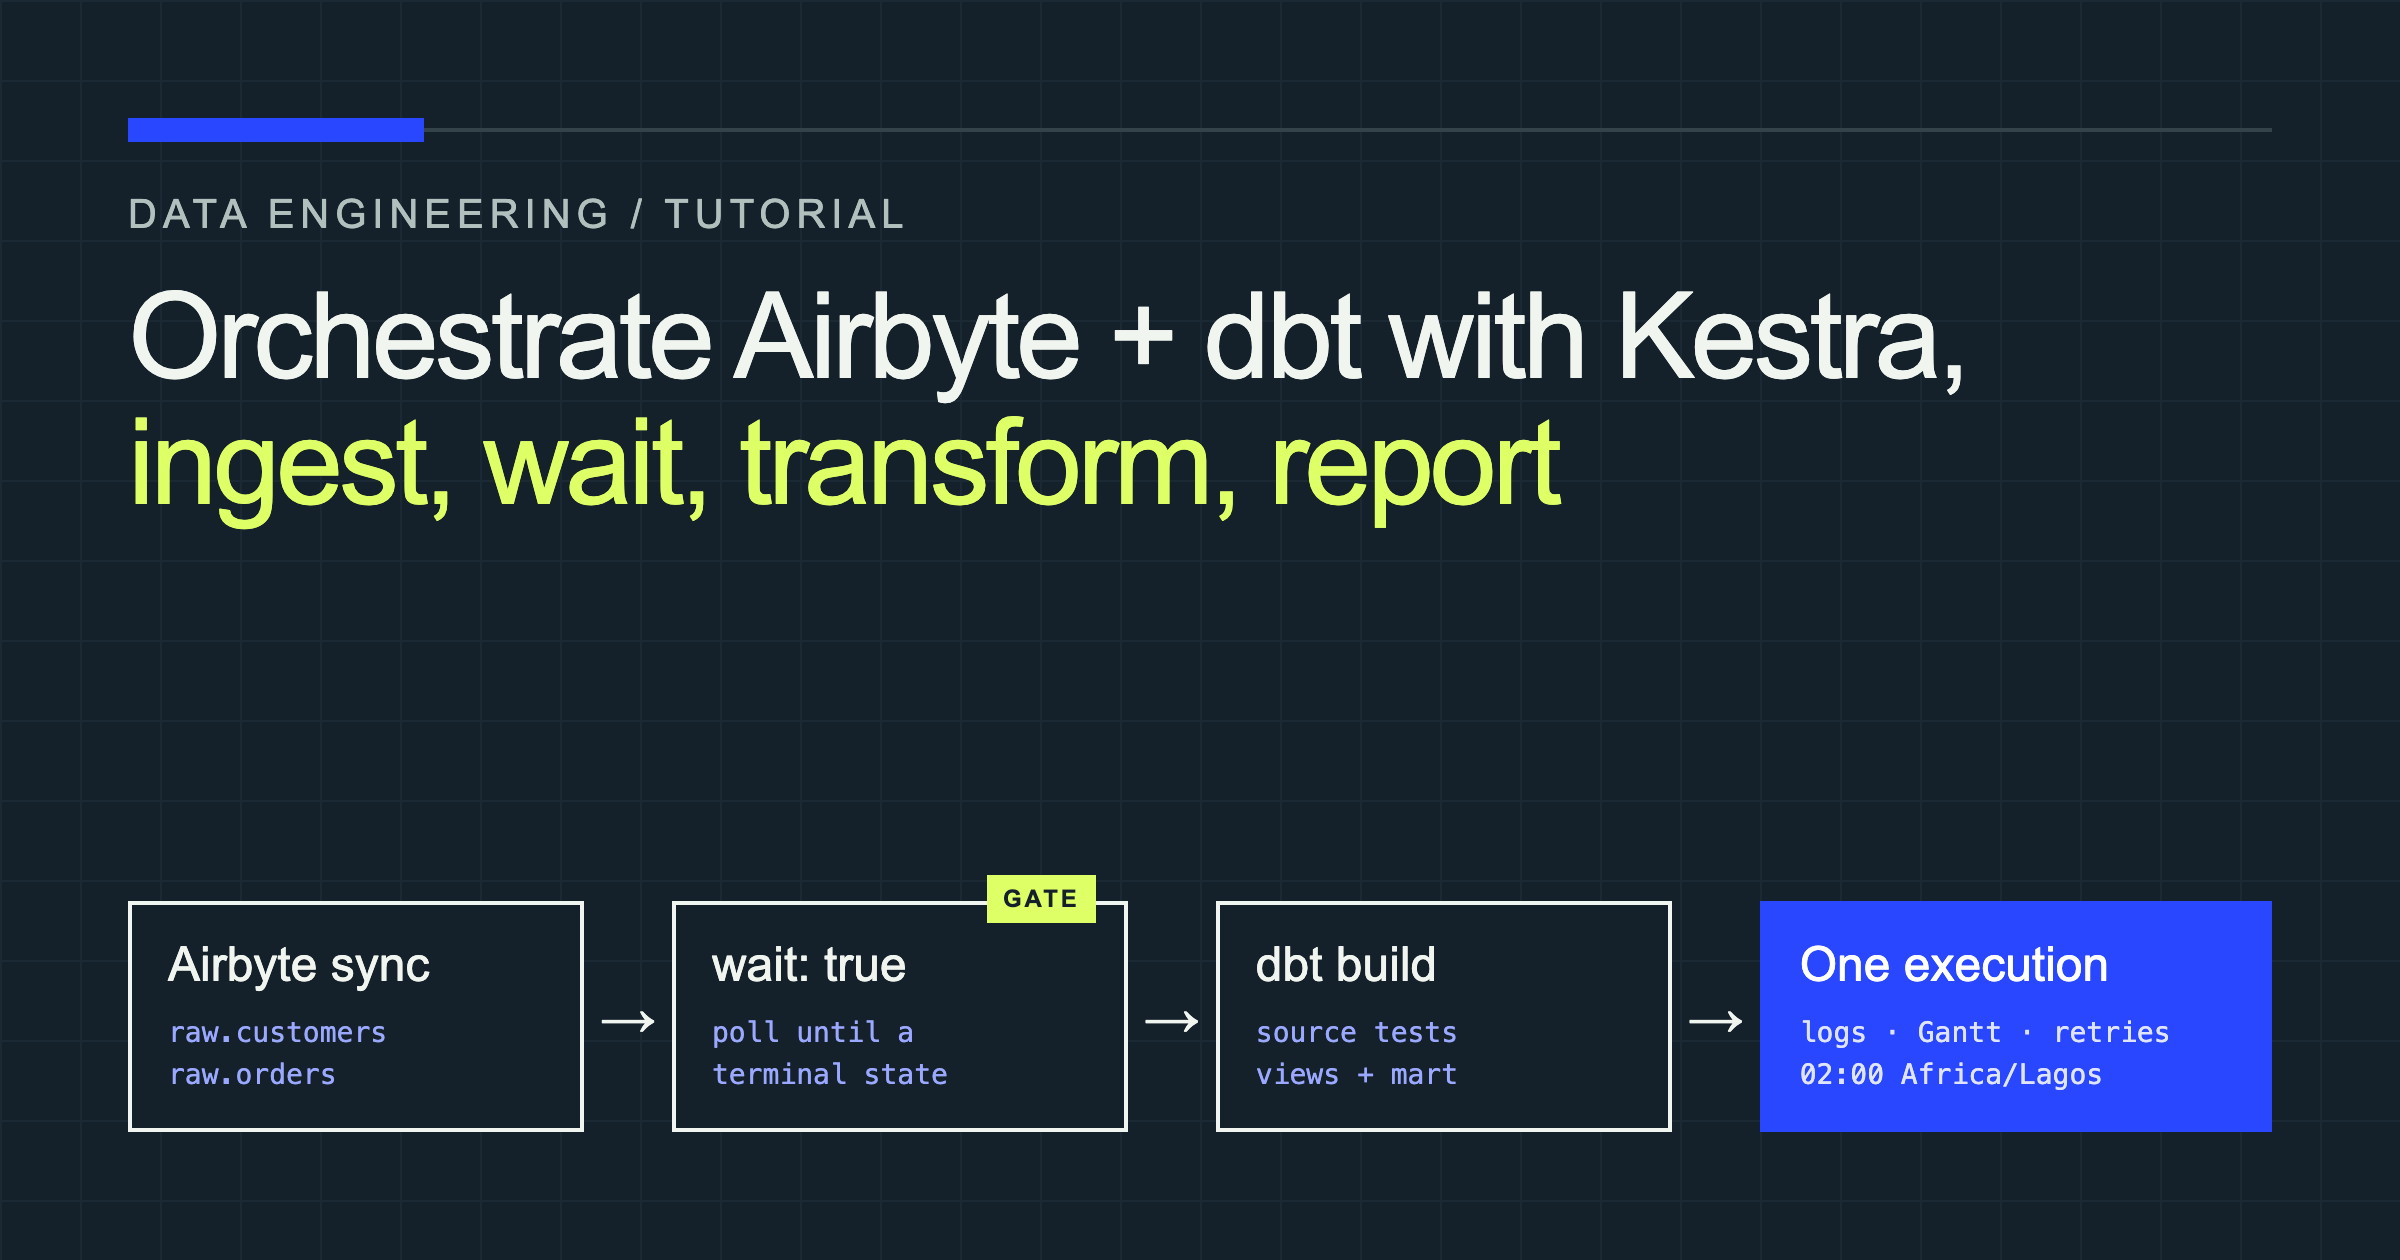
Orchestrate an Airbyte + dbt Pipeline with Kestra: An End-to-End Walkthrough
Build an automated ELT pipeline that runs an Airbyte sync, waits for completion, executes dbt models, and reports status through Kestra.
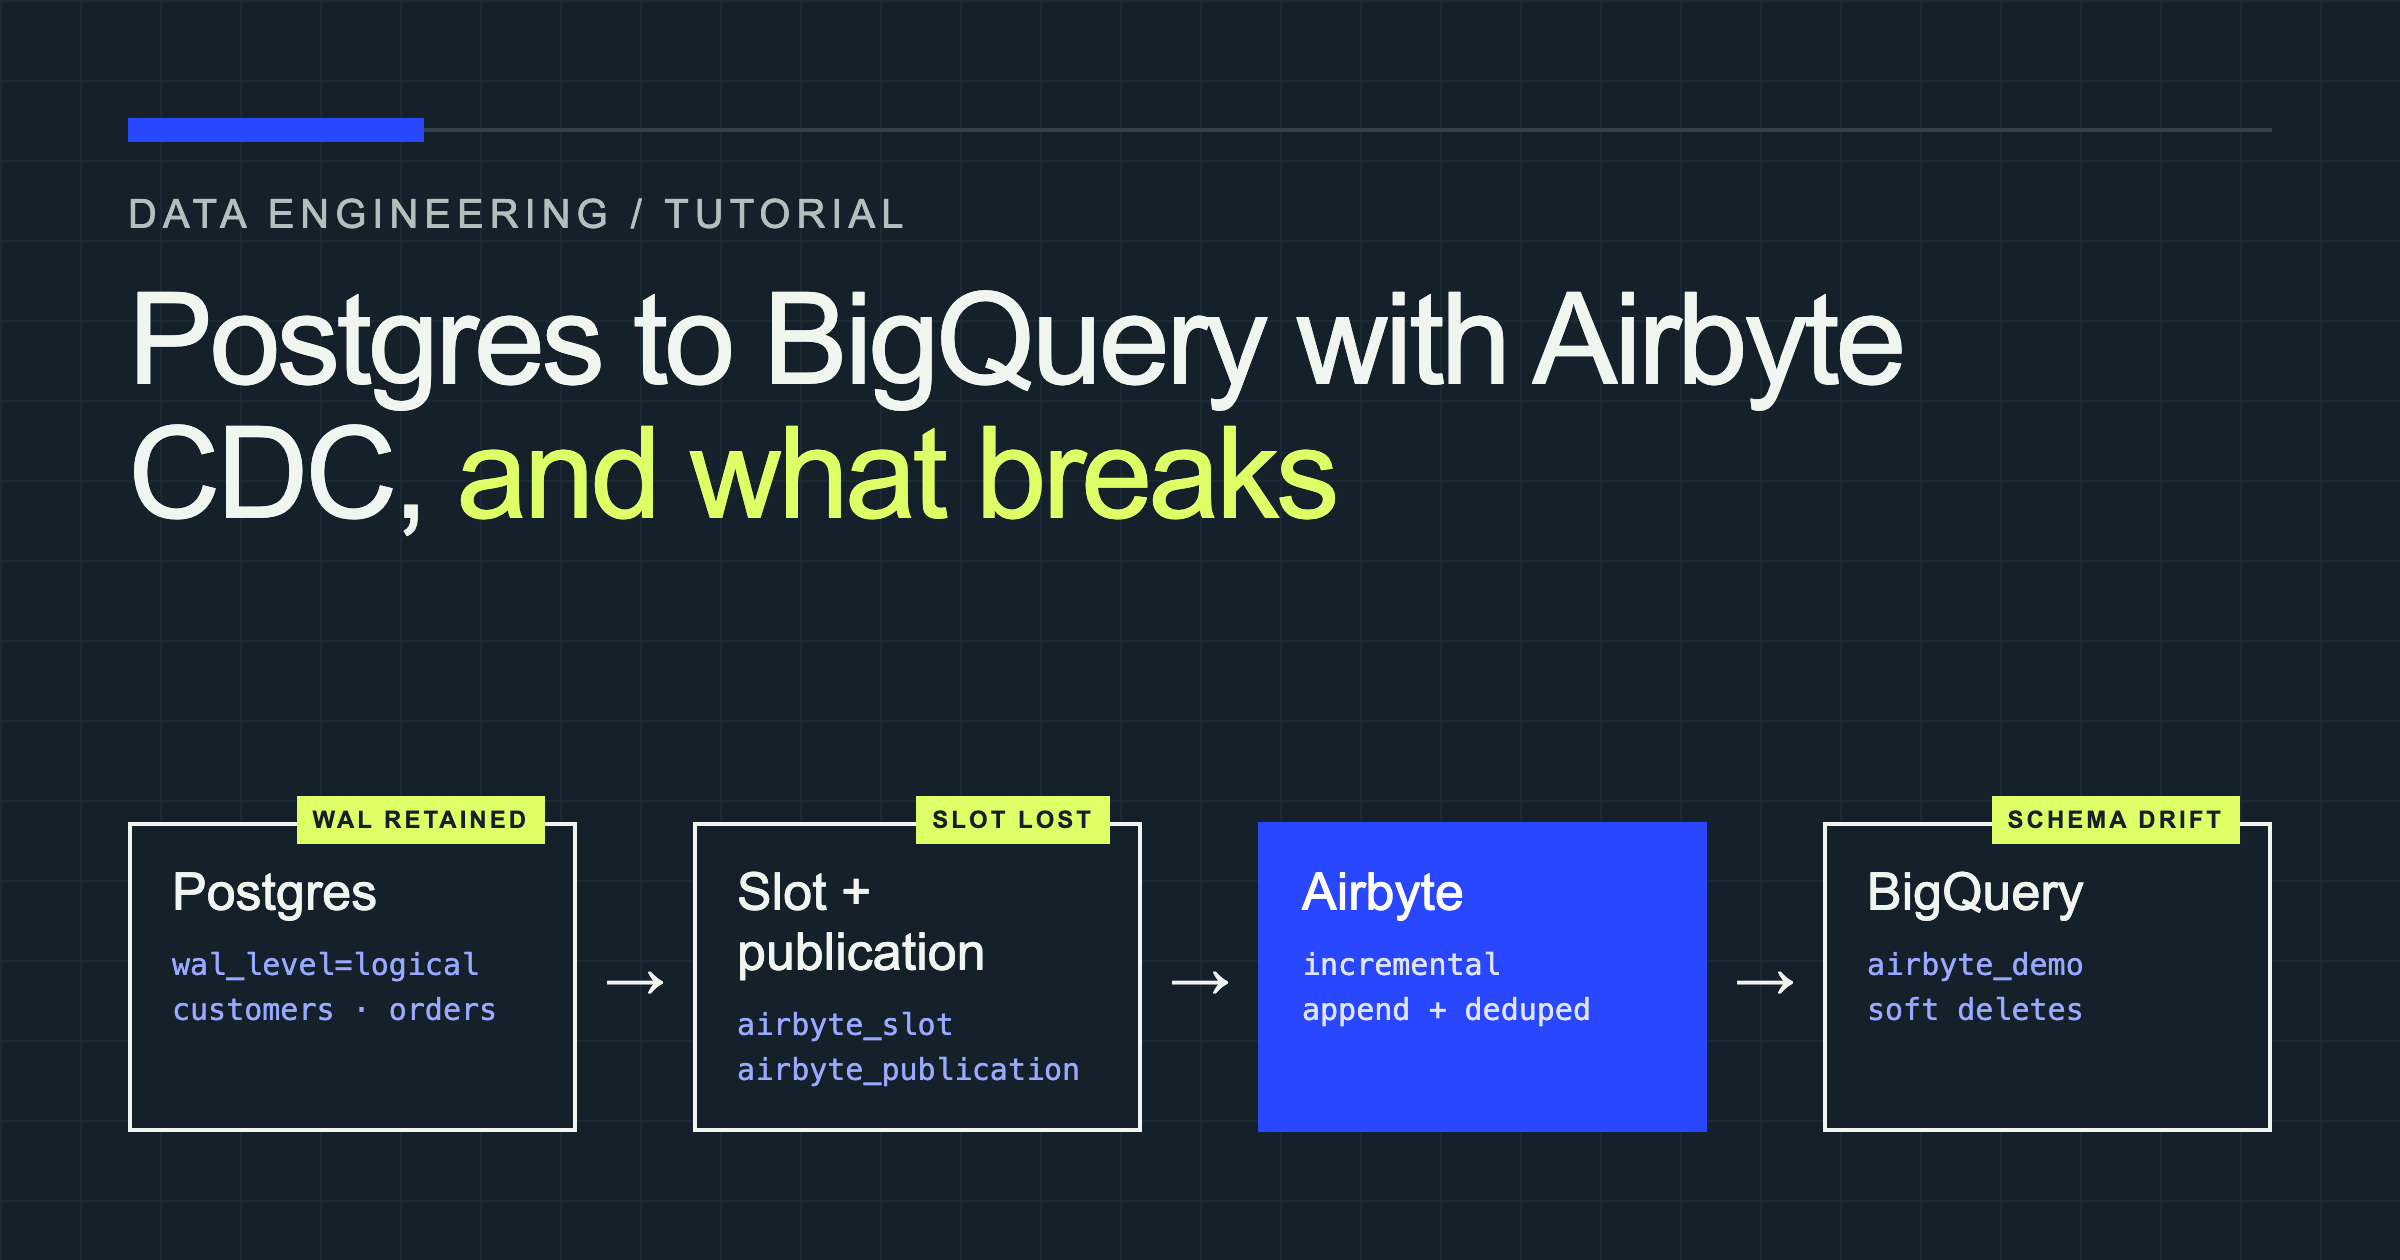
Sync Postgres to a Data Warehouse with Airbyte in 30 Minutes (and What Breaks)
Set up Postgres-to-BigQuery replication with Airbyte CDC, then diagnose six failures involving WAL, permissions, data types, keys, and schema changes.
No matches in this set.
Clear a filter or try another combination.