Data engineering / Tutorial
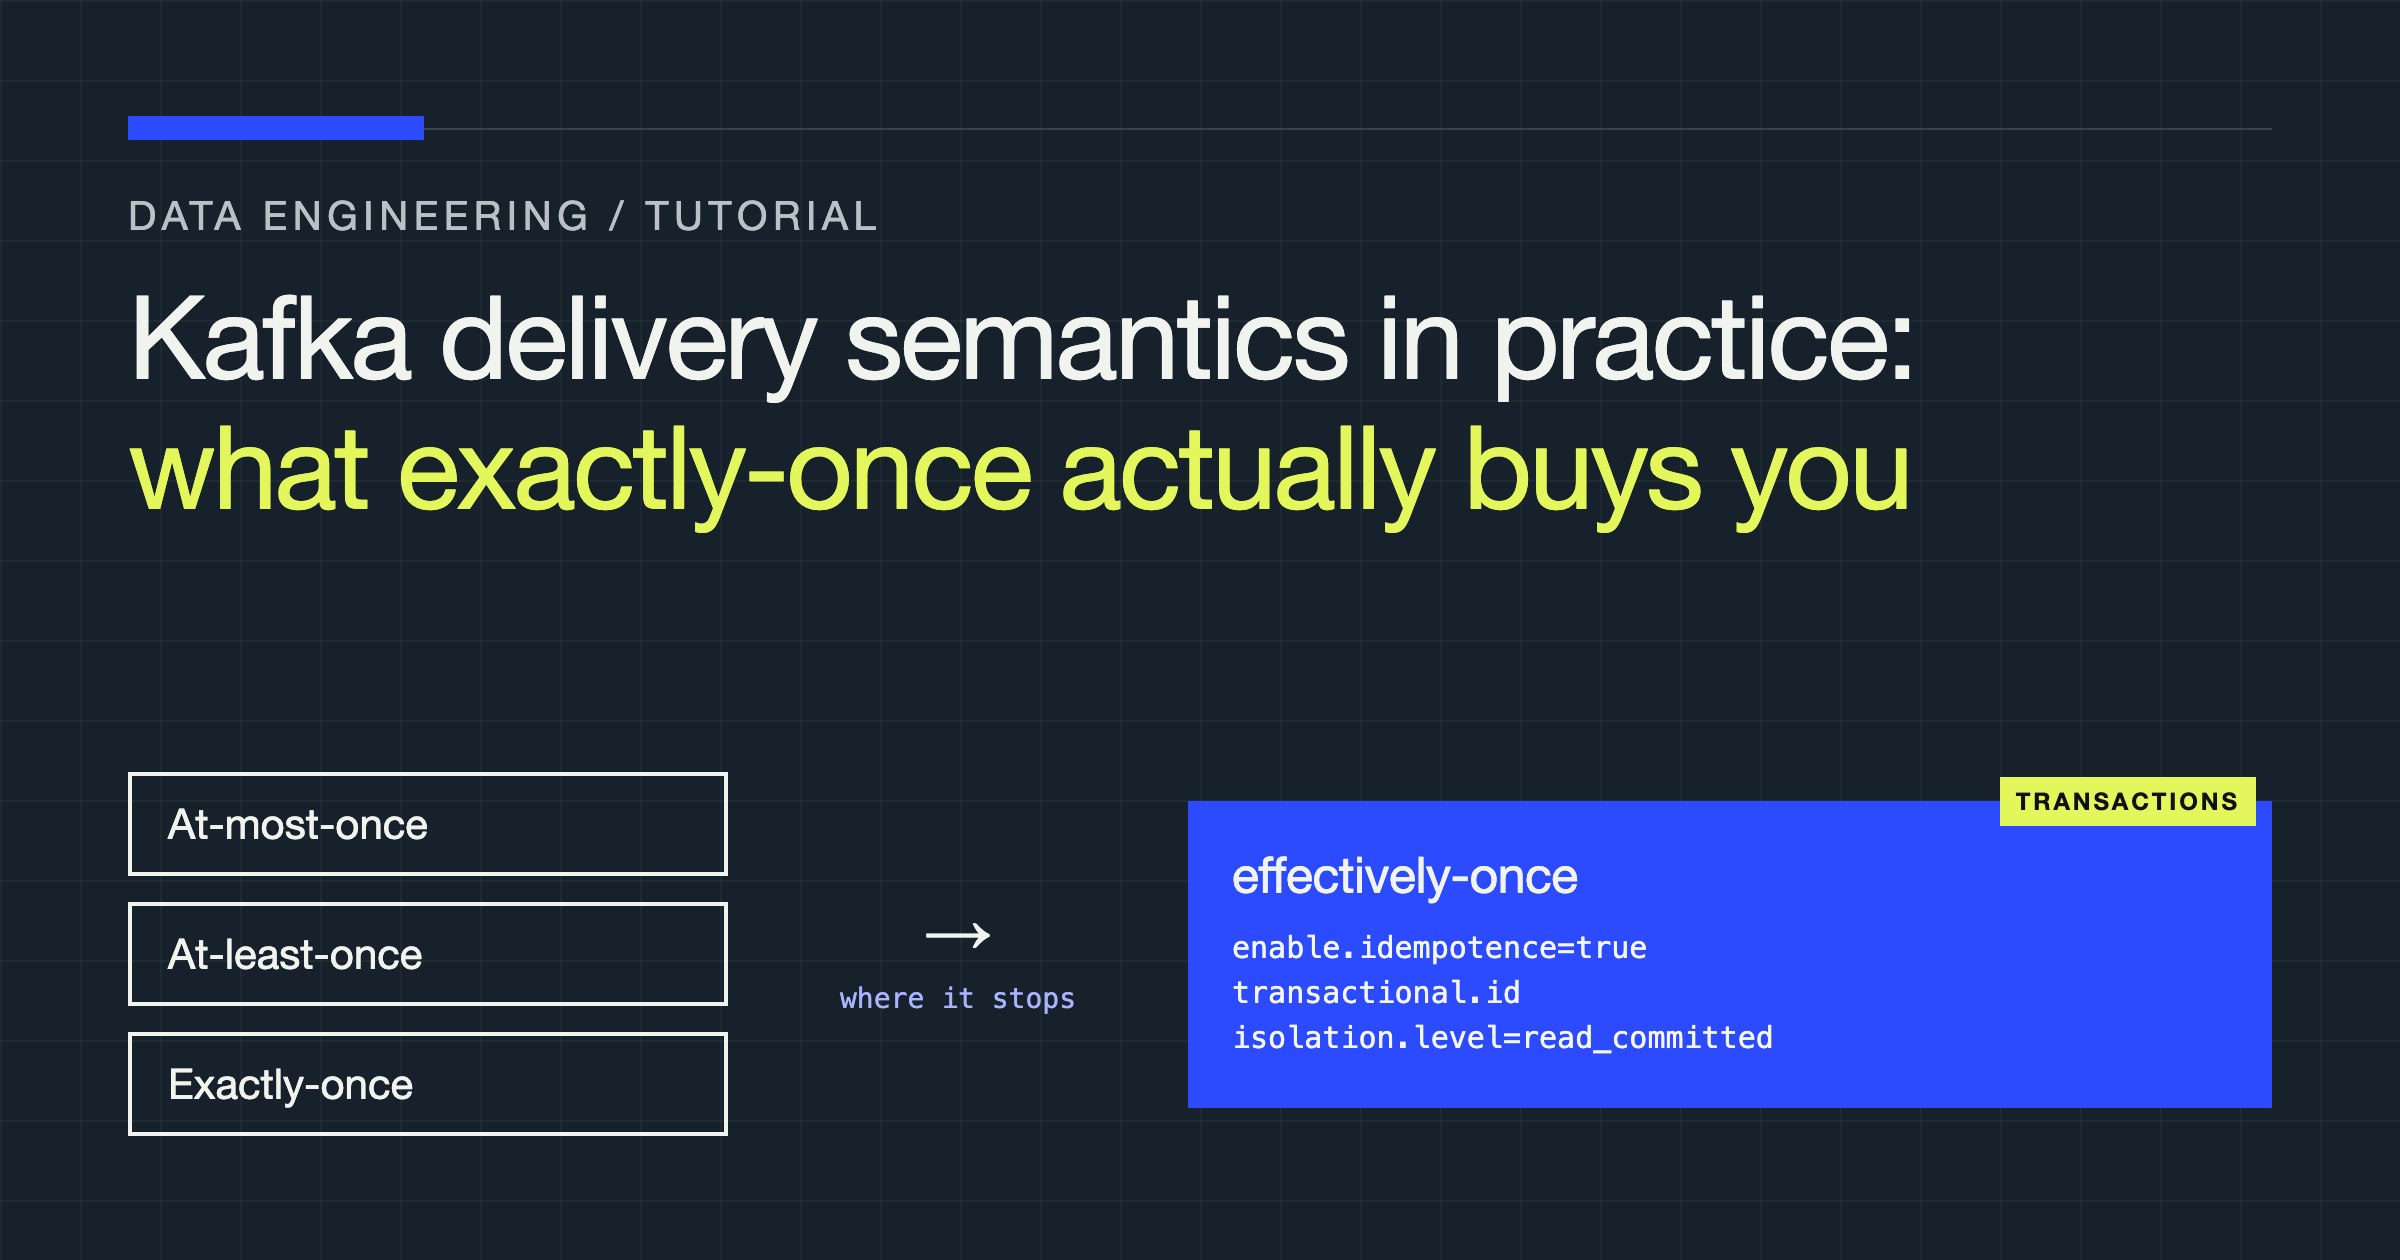
Kafka Delivery Semantics in Practice: What Exactly-Once Actually Buys You
At-most-once, at-least-once, and exactly-once in Kafka, precisely: which configurations deliver which guarantee, where exactly-once stops, and what to build instead.
You will decide, for a real pipeline, which delivery guarantee you actually need — and configure Kafka to provide exactly that, no more and no less. Along the way you will see why “exactly-once” is the most misunderstood phrase in streaming: it is a real feature with a precise, narrow scope, and most systems that claim it are actually running at-least-once with deduplication, which is often the better engineering answer anyway.
The three semantics, defined by failure
Forget the marketing versions. Delivery semantics describe what can happen when something crashes mid-flight:
- At-most-once: a message may be lost, but is never delivered twice. The consumer commits its offset before (or independently of) processing. Crash after commit, before processing: the message is gone.
- At-least-once: a message is never lost, but may be delivered more than once. The consumer processes, then commits. Crash after processing, before commit: the message is redelivered and processed again.
- Exactly-once: each message’s effect is applied once, even across crashes. Note the word effect. Nobody can stop a network from retrying; what can be controlled is whether the retry causes a second effect.
Every configuration choice in Kafka is a position on this triangle. There is no configuration that escapes it; there are only configurations whose tradeoffs you have chosen on purpose.
| Guarantee | Producer side | Consumer side | Duplicates? | Loss? | Typical use |
|---|---|---|---|---|---|
| At-most-once | acks low, retries off | Commit offsets before processing | No | Yes | Metrics, telemetry where gaps are acceptable |
| At-least-once | acks=all, retries on | Process, then commit offsets | Yes | No | The default for most pipelines |
| Exactly-once (Kafka-to-Kafka) | Idempotent + transactional producer | isolation.level=read_committed | No visible effects | No | Stream processing entirely inside Kafka |
| Effectively-once (to external systems) | acks=all, retries on | Idempotent sink or dedupe store | Absorbed by the sink | No | Kafka-to-database/search/cache pipelines |
Why consumers see duplicates
Duplicates in an at-least-once consumer are not a bug; they are the design working as intended. Three sources account for nearly all of them:
- The commit gap. Processing finished, the offset commit did not, and the consumer crashed or was rebalanced. On restart it re-reads from the last committed offset.
- Rebalances. A consumer leaving or joining the group revokes partitions; whatever the old owner processed but had not committed gets redelivered to the new owner.
- Producer retries without idempotence. A broker acknowledgement is lost in the network, the producer retries, and the log now genuinely contains the record twice. This one is a producer-side duplicate — no consumer configuration can dedupe it, because there are two distinct records.
Source 3 is why the idempotent producer matters. With enable.idempotence=true, the producer attaches a producer ID and sequence numbers, and the broker rejects retry duplicates within a session. It removes an entire class of duplicates at zero application cost. Turn it on everywhere; there is no good reason to run without it. But understand its limit: idempotence covers a single producer session writing to a single partition. It does not dedupe across producer restarts, and it does nothing about consumer-side redelivery.
Transactions: what exactly-once actually is
Kafka’s exactly-once semantics (EOS) are delivered by transactions, and their scope is specific: they make a consume → process → produce cycle atomic when the input and output are both Kafka topics, including the consumer’s offset commit as part of the transaction.
Properties props = new Properties();
props.put(ProducerConfig.BOOTSTRAP_SERVERS_CONFIG, "broker:9092");
props.put(ProducerConfig.ENABLE_IDEMPOTENCE_CONFIG, "true");
props.put(ProducerConfig.TRANSACTIONAL_ID_CONFIG, "billing-processor-1");
props.put(ProducerConfig.ACKS_CONFIG, "all");

KafkaProducer<String, String> producer = new KafkaProducer<>(props);
producer.initTransactions();

// Consumer is configured separately with:
//   enable.auto.commit=false
//   isolation.level=read_committed   <-- consumers only see committed records

while (true) {
    ConsumerRecords<String, String> records = consumer.poll(Duration.ofMillis(200));
    producer.beginTransaction();
    for (ConsumerRecord<String, String> record : records) {
        String result = transform(record.value());
        producer.send(new ProducerRecord<>("enriched-events", record.key(), result));
    }
    // The offsets ride inside the same transaction as the output records.
    producer.sendOffsetsToTransaction(currentOffsets(records), consumerGroupMetadata);
    producer.commitTransaction();
}
Three facts about this machinery that determine whether it helps you:
- Downstream consumers must use
isolation.level=read_committed. With the defaultread_uncommitted, they will read records from transactions that later abort — exactly-once theatre, at-least-once reality. transactional.idfences zombies. An old producer instance with the same transactional ID gets fenced off when a new one registers, so a hung process cannot wake up and write into the topic later. This is a genuine distributed-systems guarantee, and it is doing real work in the design.- The atomicity ends at Kafka’s boundary. The moment your processing writes to a database, calls an API, or sends an email, that side effect is not in the transaction. A crash can leave the external write done and the Kafka transaction aborted, or vice versa. EOS does not extend there, and no producer setting makes it extend there.
Where your pipeline actually ends: effectively-once
For Kafka-to-external-system pipelines — which is most of them — the industry-standard answer is at-least-once delivery plus an idempotent sink, often called effectively-once:
- Upsert on a natural key. If the sink write is
INSERT ... ON CONFLICT DO UPDATEkeyed by the entity’s primary key, redelivery is harmless. This is the single most valuable pattern in this article. - Dedupe table. Where upserts do not fit, record processed message IDs (or source coordinates like partition + offset, or a business idempotency key) in the same database transaction as the effect. On redelivery, the dedupe record proves the effect already happened. The dedupe check and the effect must commit atomically — that atomicity is what you are actually buying.
- Idempotency keys on API calls. When the side effect is an HTTP call, pass a stable key derived from the message (not a random UUID per attempt) so the receiving system can dedupe. Payments APIs popularised this pattern because they had no choice.
Note what happened conceptually: exactly-once was never achieved by delivering once. It was achieved by making delivery-twice indistinguishable from delivery-once. That reframing is liberating — it works with any broker, any sink, and any failure mode, including the ones Kafka transactions cannot touch.
Kafka Streams and the managed path
If your processing lives entirely inside Kafka, Kafka Streams (and equivalent frameworks) wire up transactions, read_committed consumption, and offset handling for you behind a single processing.guarantee=exactly_once_v2 setting. This is the one place EOS is close to free, and for topic-to-topic enrichment, filtering, and aggregation pipelines it is the right default. The caveats are the same boundary caveats: state stores and changelogs are inside the guarantee; anything your code calls out to is not. A Streams app that writes to an external database in a foreach has quietly exited exactly-once through the side door.
A worked decision
Make this concrete with an order-events pipeline: orders are published to Kafka, a processor enriches each order, and the result is stored in Postgres for the operations team to query. Walk the legs separately. The publish leg wants acks=all and the idempotent producer, because losing an order event is unacceptable and producer-retry duplicates are free to eliminate. The processing leg is a plain consumer, so its honest guarantee is at-least-once: it will occasionally see an order twice, after a rebalance if not sooner. The storage leg is where the decision lands — the processor writes with an upsert keyed on the order ID, so the second delivery updates the same row to the same values and the operations team never knows it happened. No transactions were configured, nothing claims exactly-once, and yet the observable outcome — each order’s enriched state applied exactly once — is precisely what the business asked for. If the same pipeline also charged a card through an external API, the analysis would add one more leg with its own answer: a stable idempotency key derived from the order ID, passed on every attempt, so the payment provider dedupes what Kafka cannot. Leg by leg, weakest link by weakest link — that is the whole method.
Failure modes the brochures skip
- Transaction timeouts on slow processing. Transactions that stay open too long get aborted by the broker. Batch sizes and per-batch processing time must be tuned together; a slow downstream call inside the loop can abort transactions at exactly your peak load.
- Poison pill records. A record that always crashes processing will redeliver forever under at-least-once, blocking its partition. Dead-letter queues with a bounded retry policy are not optional in production consumers.
- Rebalance storms. Long processing batches delay polls, trigger rebalances, cause redelivery, which makes batches slower — a feedback loop. Keep per-poll work bounded and commit incrementally where the semantics allow.
- Ordering assumptions. Guarantees apply per partition. “Exactly-once” says nothing about cross-partition ordering, and transactional writes do not create a global sequence your consumers can rely on.
Verdict
Decide from the sink backwards. If your sink can upsert on a natural key — most databases, search indexes, and warehouses can — run the boring, robust stack: idempotent producer, acks=all, at-least-once consumption, offsets committed after writes, idempotent sink. You get effectively-once outcomes without transaction overhead or its operational sharp edges.
Reserve true Kafka transactions for pipelines that begin and end in Kafka, ideally via Kafka Streams, where the guarantee is complete rather than partial. Use at-most-once only where loss is genuinely cheaper than duplication — telemetry you sample anyway, never anything with a dollar sign or a user’s trust attached.
And retire the phrase “exactly-once” from your architecture documents unless it is followed by the words “between these two topics” or “via idempotent writes keyed on…”. Precision about the boundary is the whole game: every streaming incident in this space is, at root, a team discovering where their guarantee actually stopped.