Tag
llm
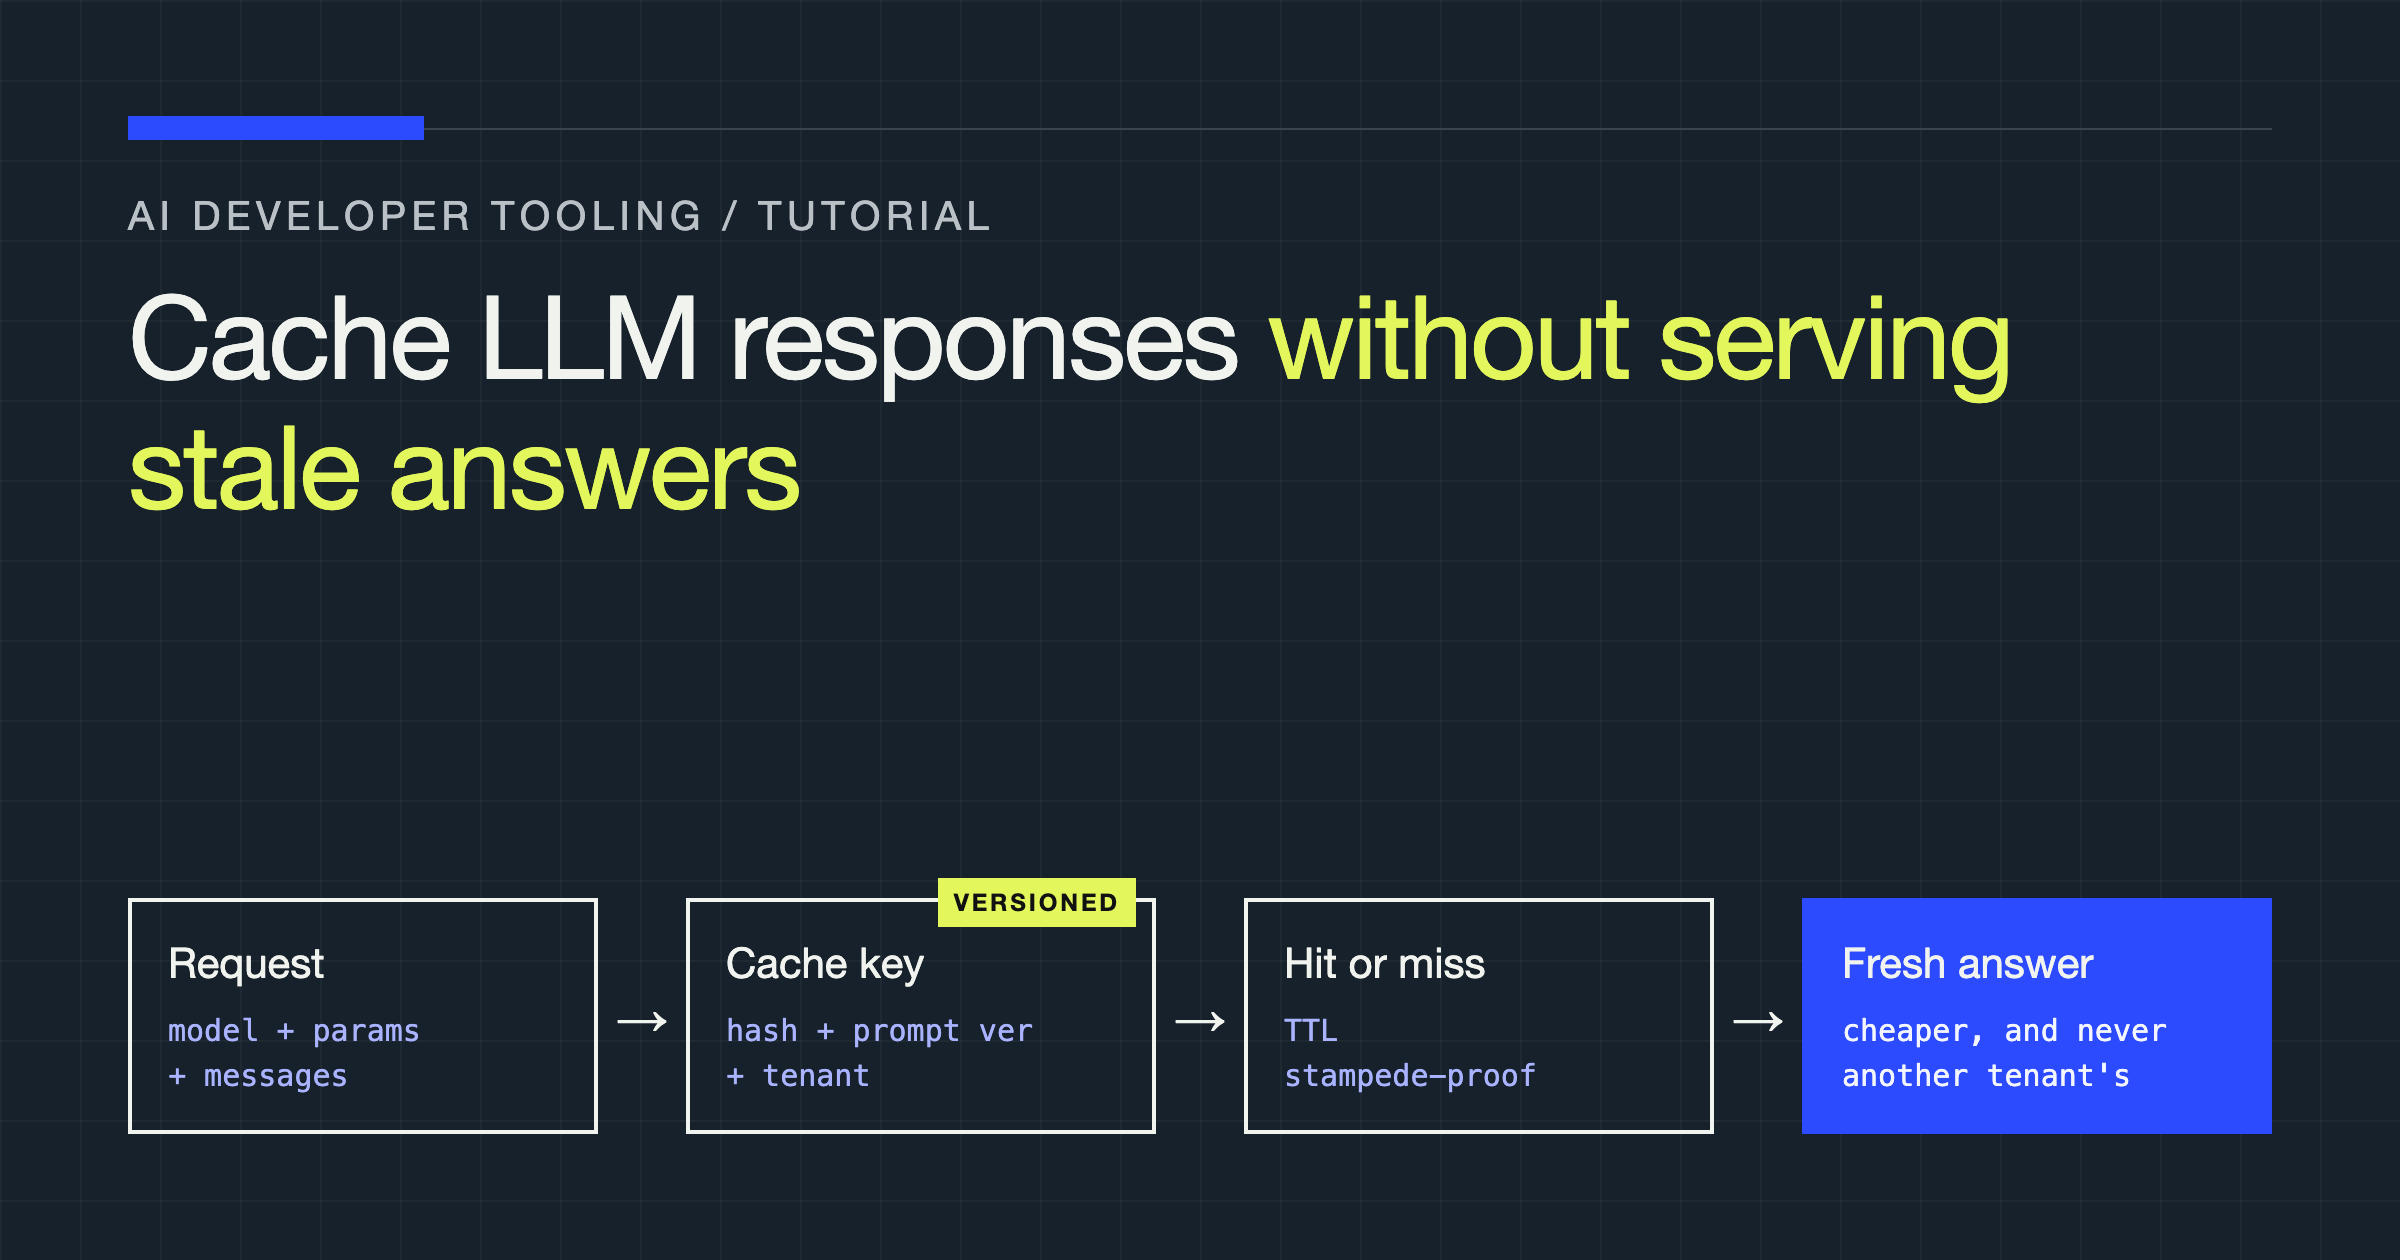
Cache LLM Responses Without Serving Stale Answers
Design an LLM response cache that actually saves money: exact-match keys, versioned prompts, tenant isolation, and the strict rules for when semantic caching is safe.
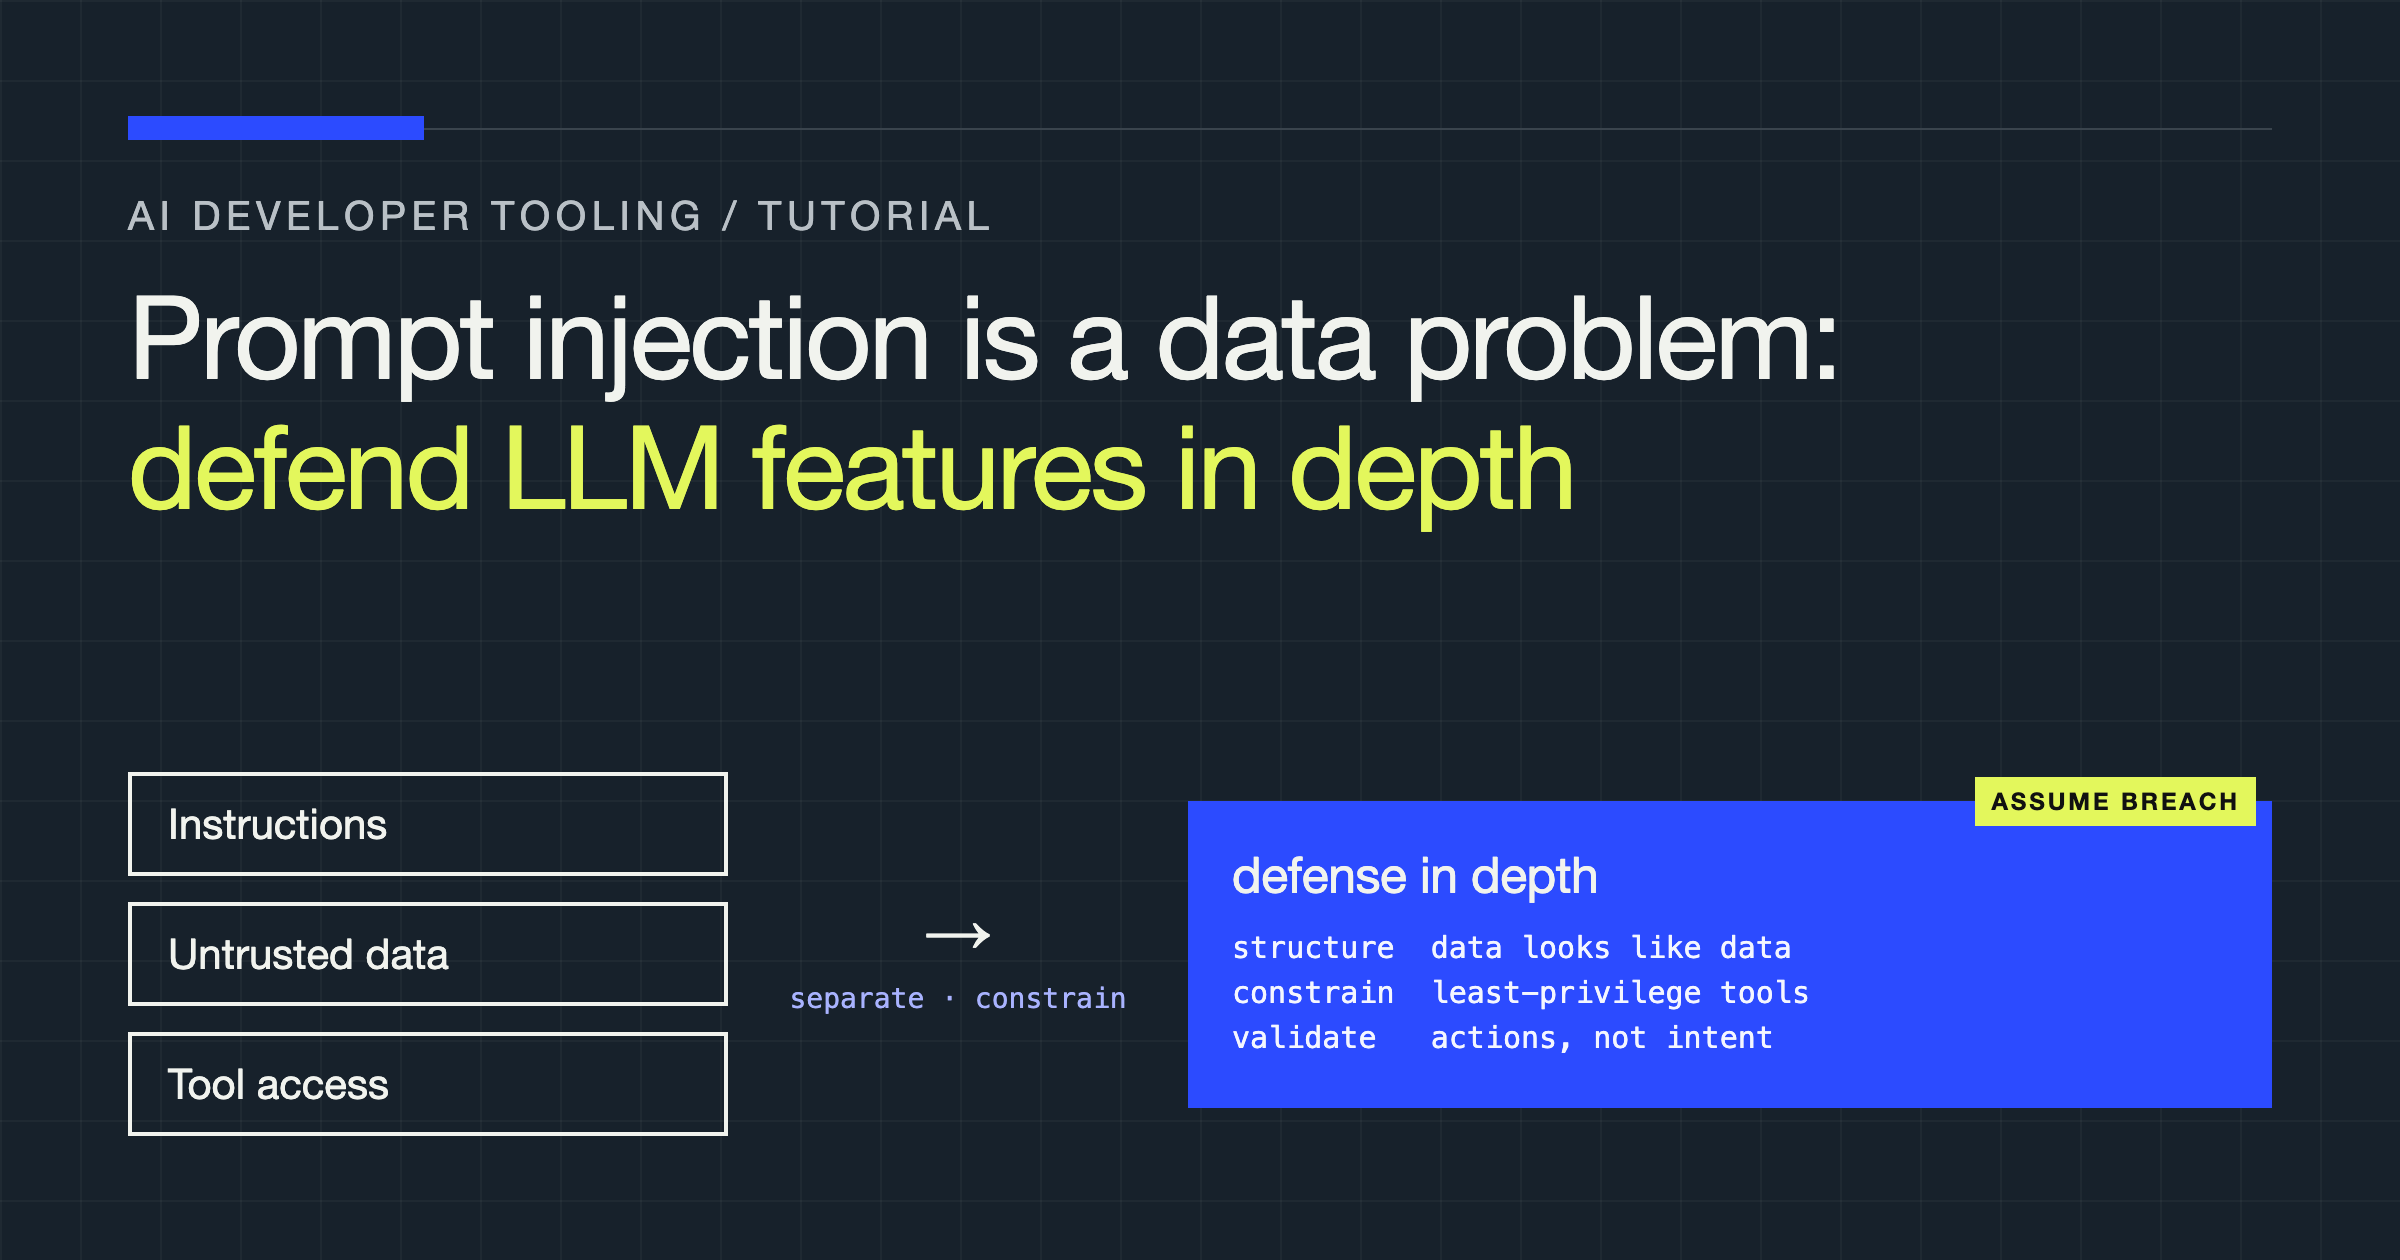
Prompt Injection Is a Data Problem: Defending LLM Features in Production
Prompt injection works because models cannot tell instructions from data. Defend in depth: separate the two, constrain tools, validate actions, and assume breach.
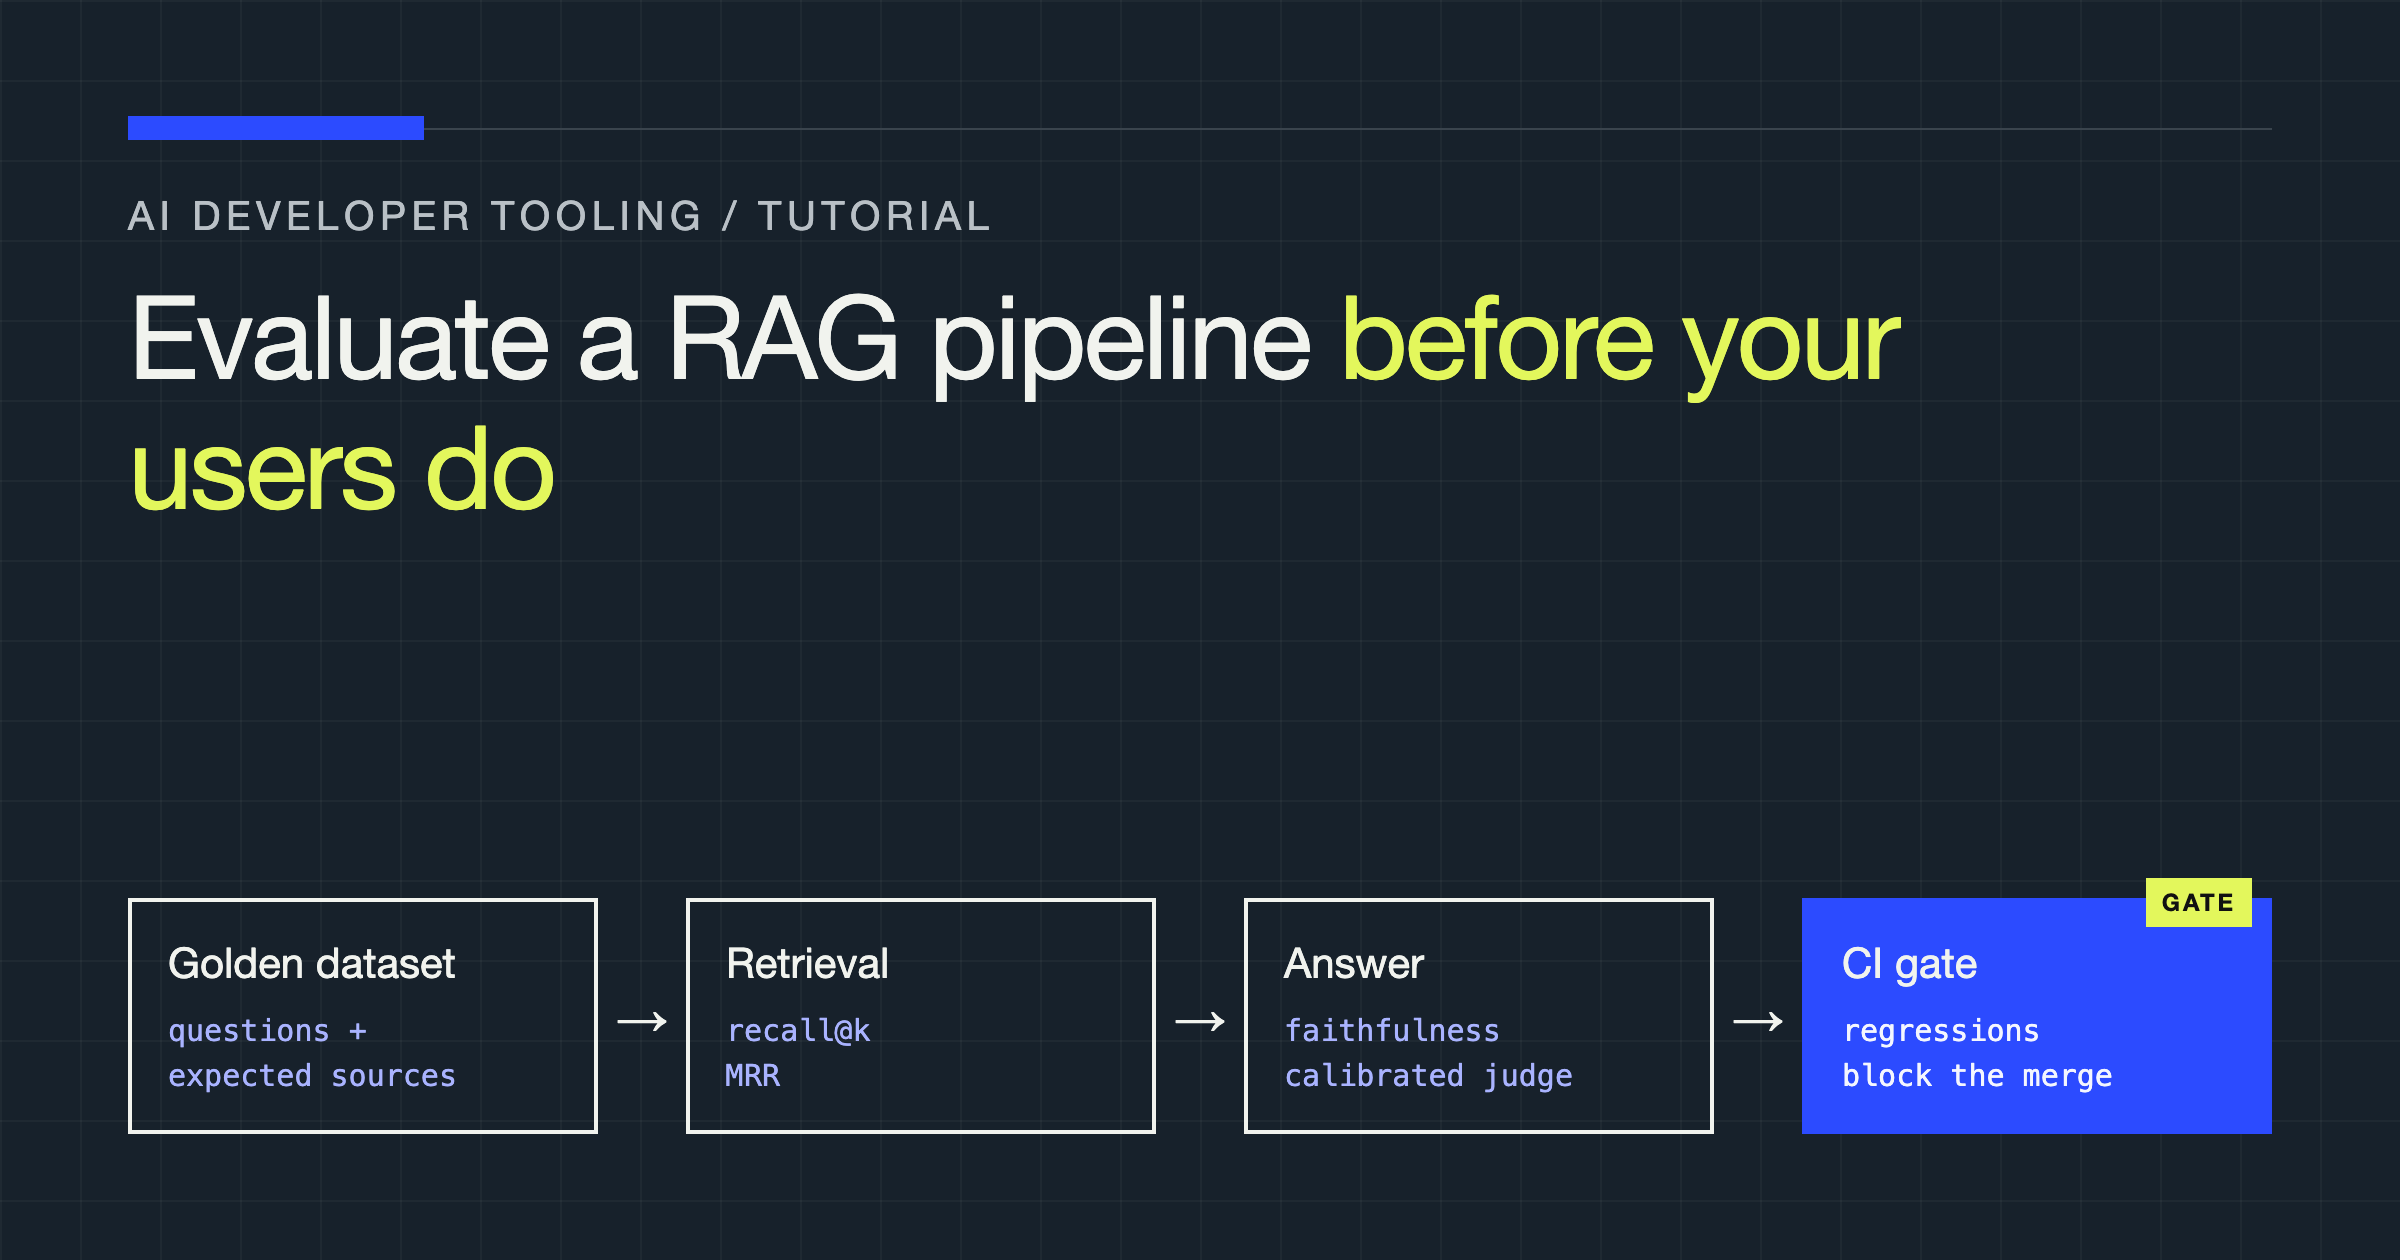
Evaluate a RAG Pipeline Before Your Users Do
Build a repeatable evaluation harness for your retrieval-augmented generation pipeline: golden datasets, retrieval metrics, faithfulness checks, and CI gates.
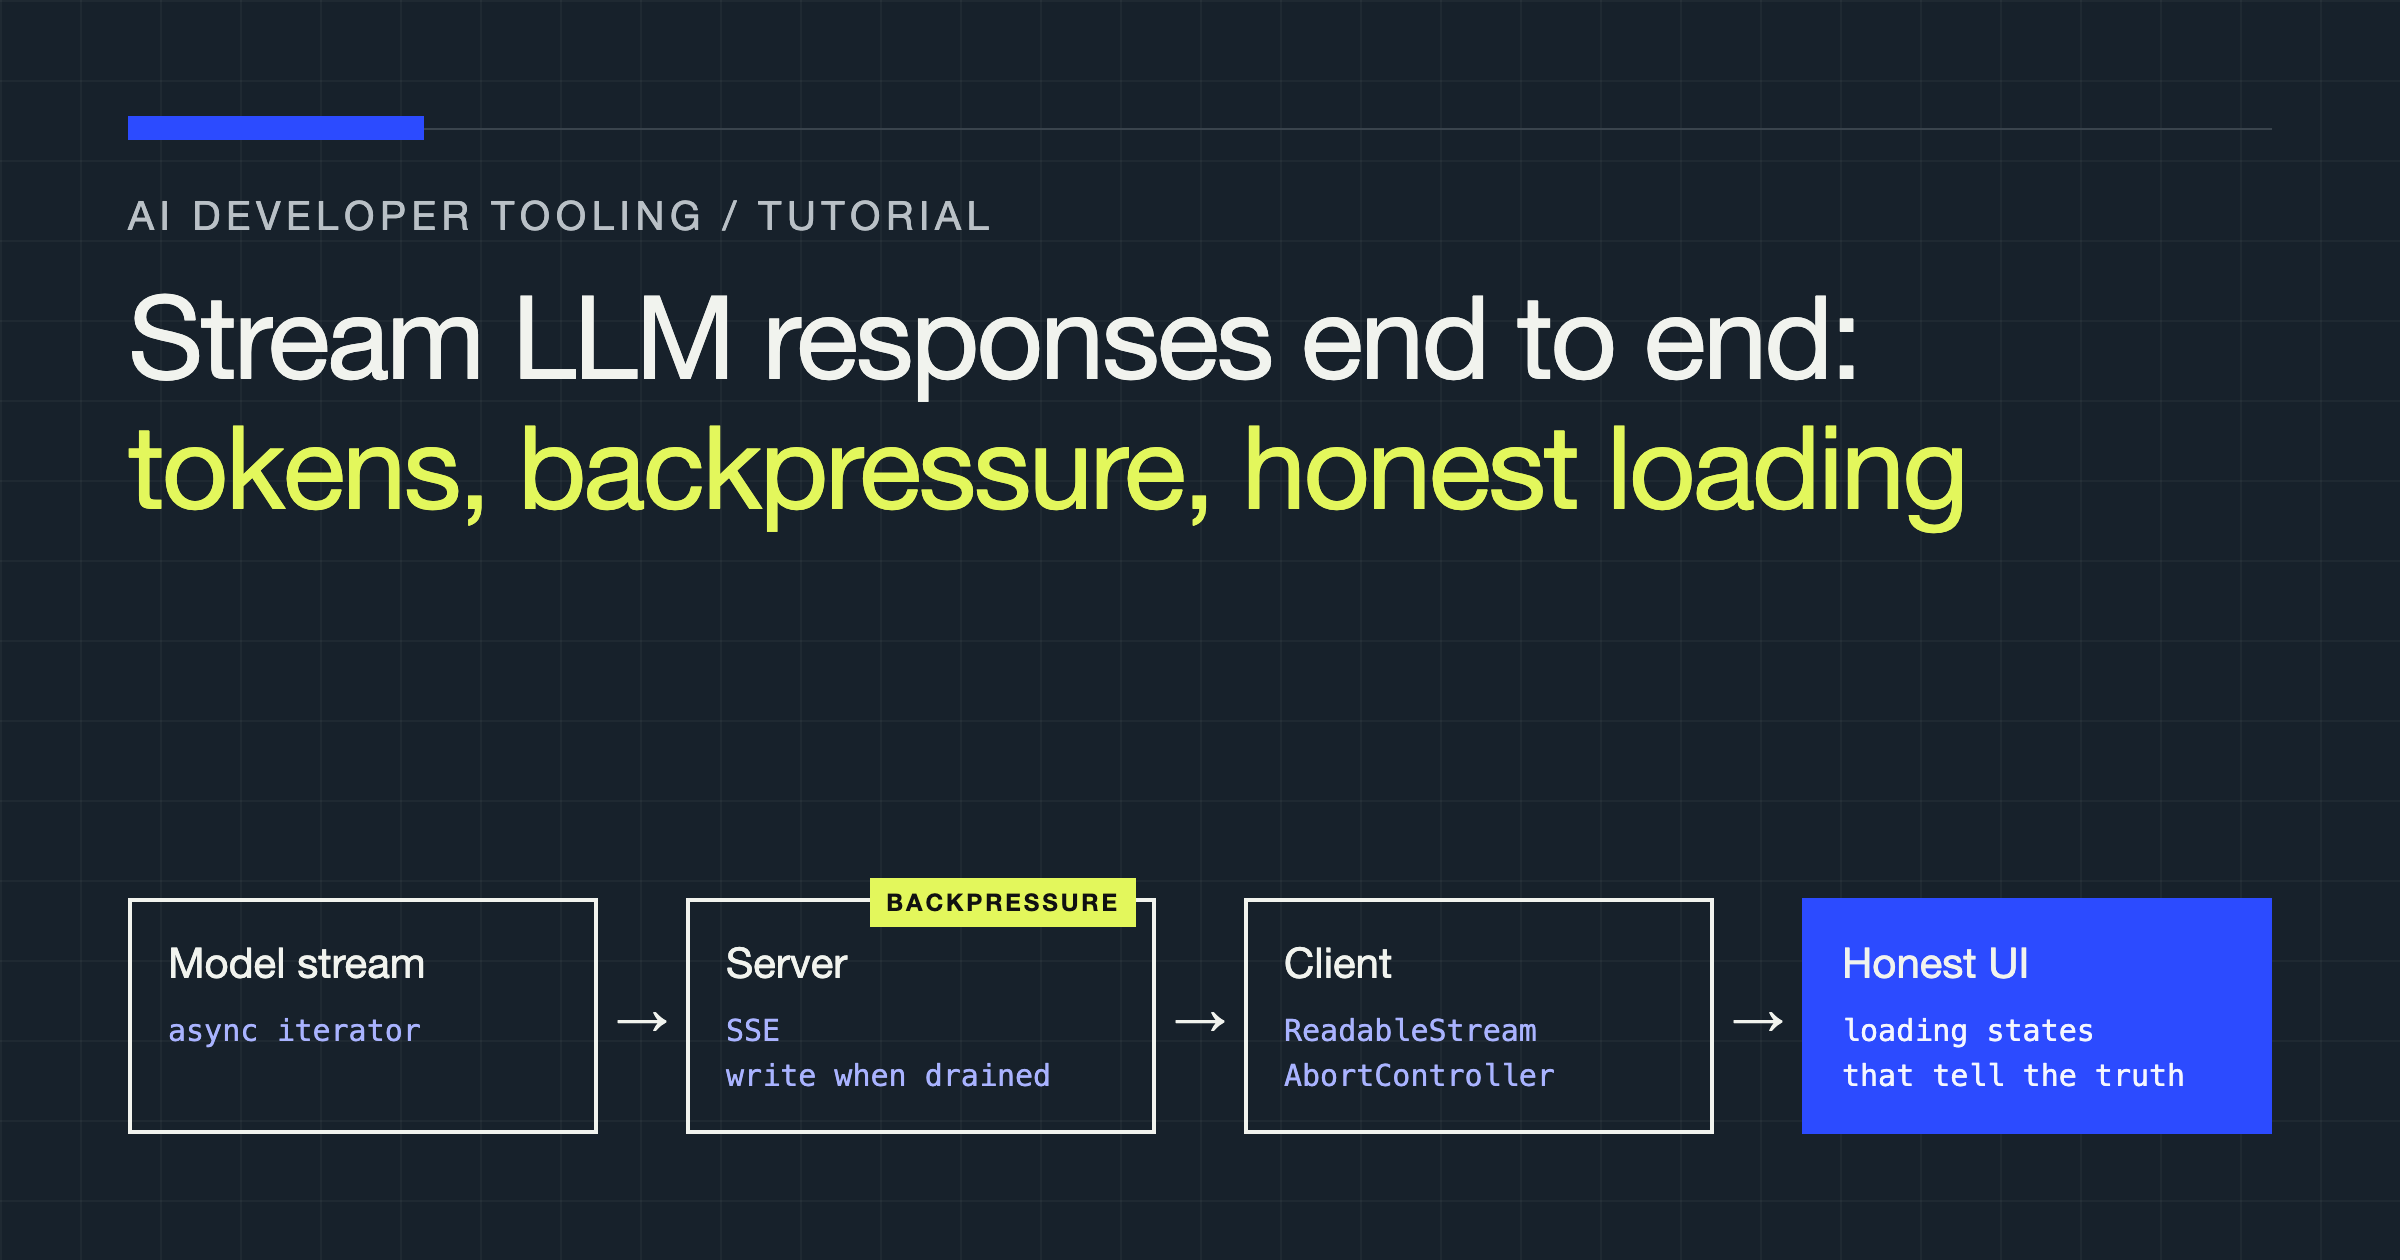
Streaming LLM Responses End to End: Tokens, Backpressure, and Honest Loading States
Build production-ready token streaming with SSE, ReadableStream, backpressure, aborts, and loading states that tell the truth.
No matches in this set.
Clear a filter or try another combination.